

GPT-6 Astra is better than GPT-5.6 Sol for complex agent workflows, difficult debugging, automation, and demanding long-context tasks. GPT-5.6 Sol is the better choice for routine coding, writing, analysis, and high-volume API workloads because it costs less while remaining competitive on well-defined tasks. In short, use Sol as the default and Astra when task failure or human correction becomes expensive.
The problem is that GPT-6 Astra costs 2.5× more than GPT-5.6 Sol at OpenAI’s Standard short-context API rates, but it is not 2.5× better for every task. Astra shows its biggest gains in agentic execution, migrations, automation, and complex reasoning, while Sol often remains more economical for routine work. The better metric is cost per successful task—not price per token alone.
GPT-6 Astra and GPT-5.6 Sol are available through LinkModel, with Astra priced at 75% of OpenAI’s corresponding Standard API token rates—a 25% discount. With one OpenAI-compatible API, one API key, and unified billing, developers can use Sol for lower-cost workloads and switch to Astra for harder tasks without rebuilding their integration.

GPT-6 Astra vs GPT-5.6 Sol: Quick Answer
For API comparisons, GPT-5.6 primarily means GPT-5.6 Sol because OpenAI states that the GPT-5.6 alias routes requests to Sol.
| Factor | Astra | Sol |
|---|---|---|
| Input price | $10/M | $4/M |
| Output price | $50/M | $20/M |
| Context window | 1.05M | 1.05M |
| Maximum output | 128K | 128K |
| Terminal-Bench | 57.9% | 37.3% |
| DeepSWE | 74.1% | 72.7% |
The practical decision is straightforward for AI API pricing comparisons:
- Use Sol by default when the task is predictable and inexpensive to retry.
- Use Astra first when failure, supervision, or incomplete execution is expensive.
- Escalate from Sol to Astra when validation fails or the task becomes agentic.
- Compare cost per completed task, not only price per million tokens.
What Changed From GPT-5.6 Sol to GPT-6 Astra?
GPT-6 Astra is designed for the hardest end-to-end work, while GPT-5.6 Sol is a lower-cost flagship model for complex professional tasks. Both can write code, use tools, process large contexts, and produce professional content, but Astra places more emphasis on autonomous execution and sustained problem-solving.
Astra Is an Agent Upgrade
Astra’s clearest advantage appears when a task requires the model to explore an unfamiliar environment, select tools, diagnose the root cause, make changes, validate the result, and recover from an unsuccessful attempt.
That is different from asking for an explanation, isolated function, short report, or clearly specified edit. Sol already handles many of those tasks effectively.
In our research, Astra created the most value when it needed to inspect unfamiliar repositories, identify architectural causes, coordinate several actions, or continue working without constant human direction. Sol remained competitive when the implementation path was already clear.
Astra is therefore a stronger completion engine for difficult workflows, not simply a more expensive version of Sol.
Astra and Sol Have the Same Context Capacity
Both models support a 1,050,000-token context window and up to 128,000 output tokens. Earlier comparisons sometimes described Sol as having a smaller context window, but current official documentation no longer supports that distinction.
The difference is how effectively each model uses large context. Astra becomes more valuable when requirements, source files, logs, previous failures, and tool results are distributed across hundreds of thousands of tokens.
OpenAI’s GPT-6 Astra documentation lists five reasoning levels from low through max, while the GPT-5.6 Sol documentation also includes a none setting. Both support major Responses API capabilities, although individual API providers may expose a narrower feature set.
GPT-6 Astra vs GPT-5.6 Benchmarks
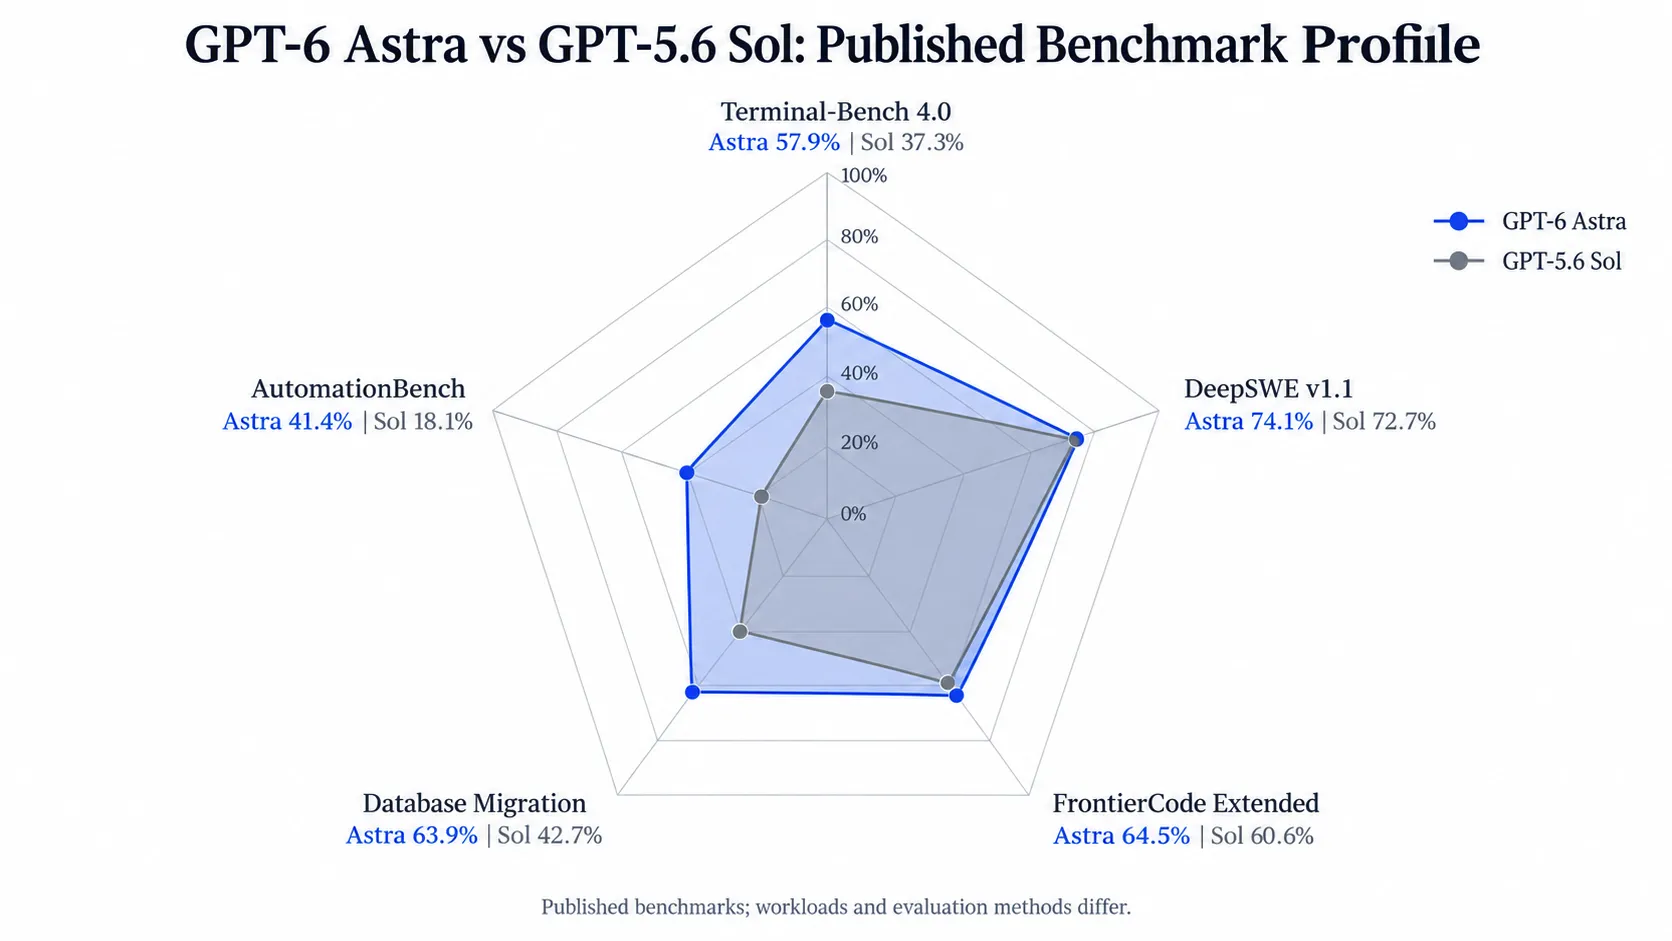
The most useful comparison is not the average benchmark score. It is the size of Astra’s advantage for each type of work.
| Benchmark | Astra | Sol |
|---|---|---|
| Terminal-Bench 4.0 | 57.9% | 37.3% |
| DeepSWE v1.1 | 74.1% | 72.7% |
| FrontierCode Extended | 64.5% | 60.6% |
| Database Migration | 63.9% | 42.7% |
| AutomationBench | 41.4% | 18.1% |
| OSWorld 2.0 | 72.6% | 65.7% |
OpenAI’s GPT-6 Astra evaluation report publishes these results under specific model, reasoning, tool, and agent-harness configurations. They provide controlled evidence but do not guarantee the same results in every application.
Agentic Work Shows the Largest Gains
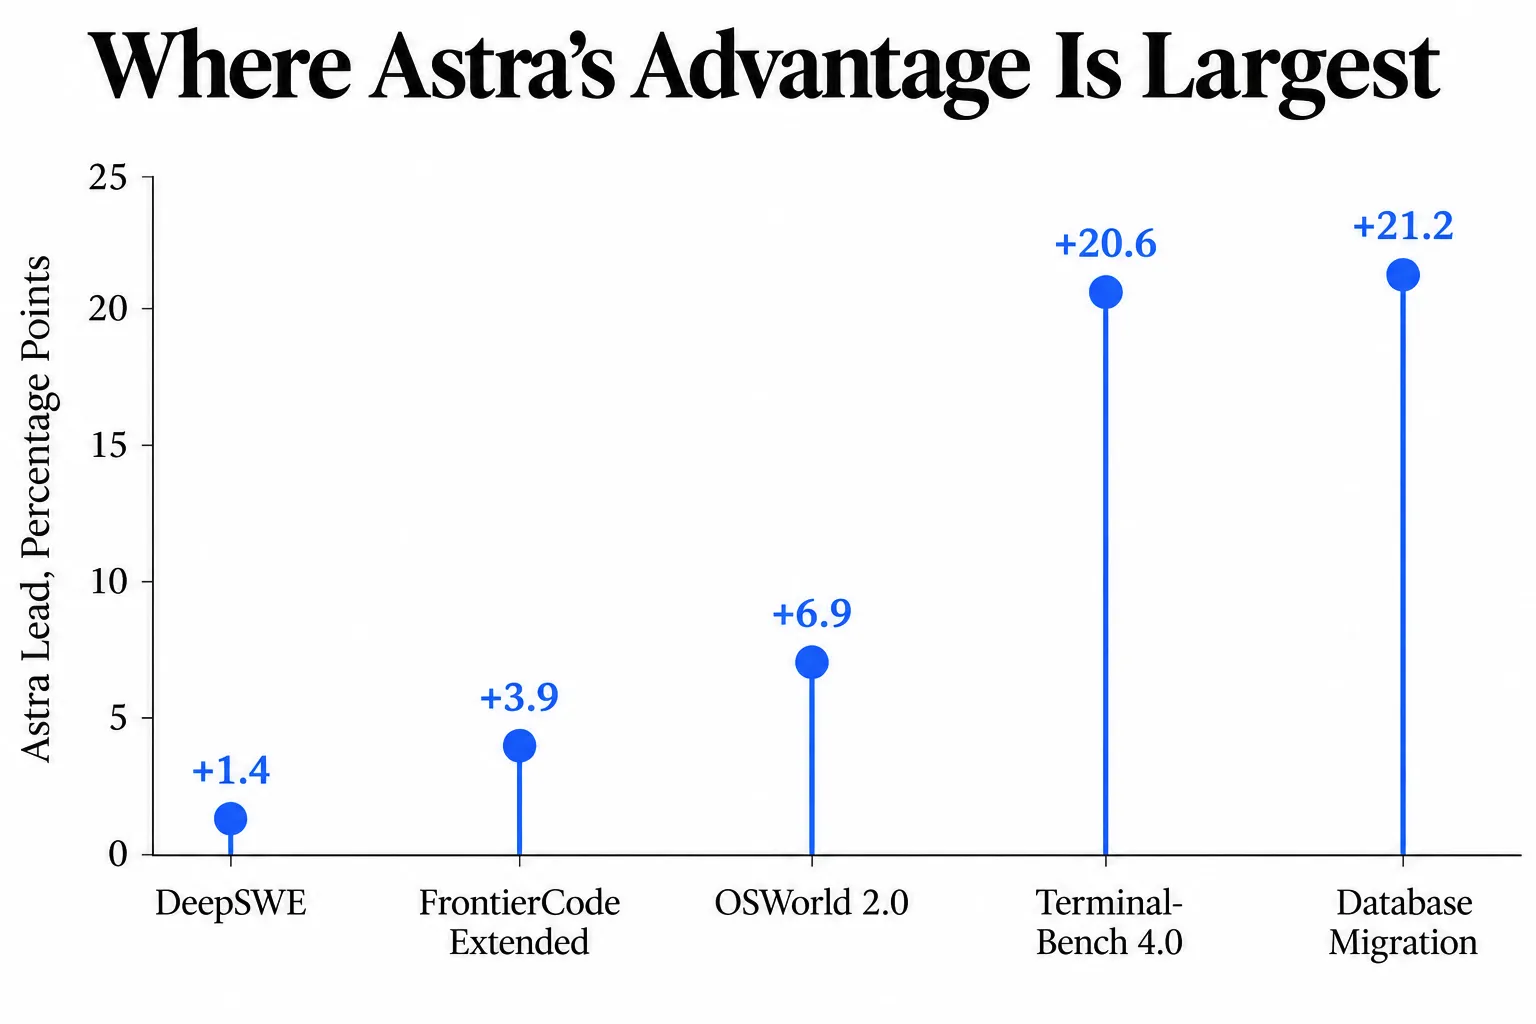
Astra leads Sol by 20.6 percentage points on Terminal-Bench 4.0, 21.2 points on Database Migration, and 23.3 points on AutomationBench.
These evaluations measure whether a model can perform dependent actions and reach a valid final state—not merely generate plausible text or isolated code.
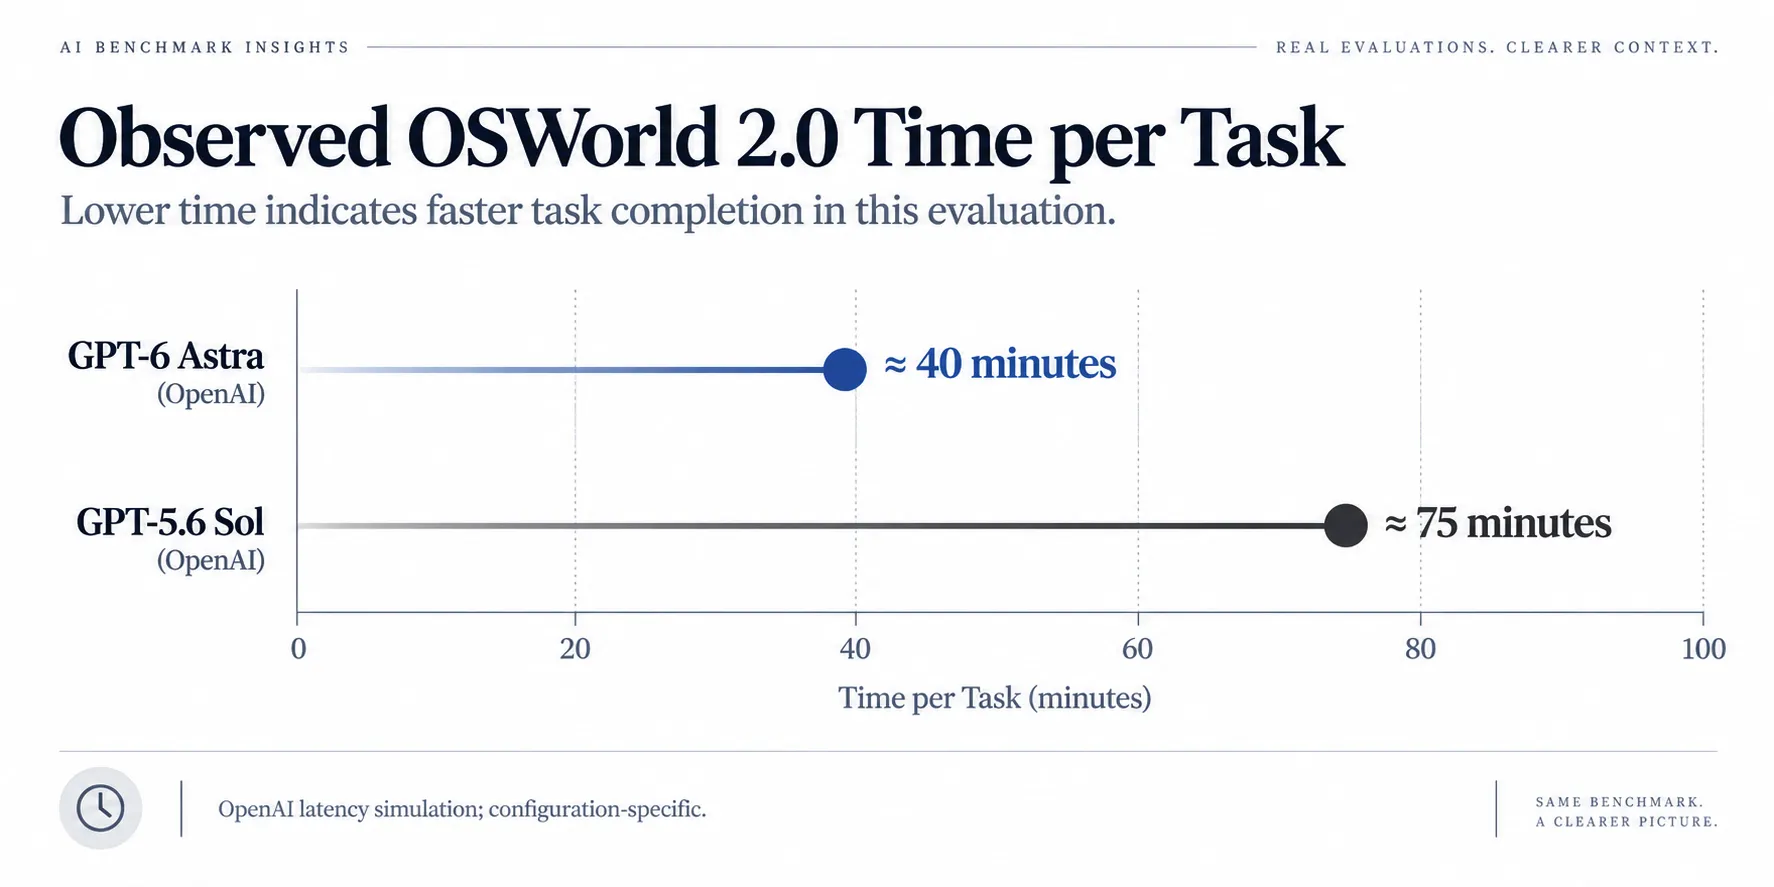
The same pattern appears in computer use. On OSWorld 2.0, Astra scored 72.6% in roughly 40 minutes per task, while Sol scored 65.7% in roughly 75 minutes. Astra required approximately 47% less time per task in that simulation.
This matters when an engineer must wait for the result, review intermediate work, or repair an incomplete run. A model that costs more per token can still create better economics if it completes more work with less supervision, which is why reducing AI API costs requires looking beyond token price alone.
Ordinary Coding Shows a Smaller Difference
Astra scored 74.1% on DeepSWE v1.1, compared with 72.7% for Sol. On FrontierCode Extended, the result was 64.5% versus 60.6%.
These differences are much smaller than Astra’s gains on terminal, automation, and migration tasks. A predictable refactor, dependency update, test-generation task, or well-specified feature may gain little from Astra’s higher token price.
In the Artificial Analysis index version reviewed for this article, its DeepSWE implementation scored 68% for Astra and 72% for Sol, even though Astra led the overall Coding Agent Index.
The result reinforces one important conclusion: coding is not a single workload. Astra performs best when coding becomes an end-to-end agent task, while Sol remains highly competitive for direct implementation.
Astra Pulls Ahead in Difficult Long-Context Work
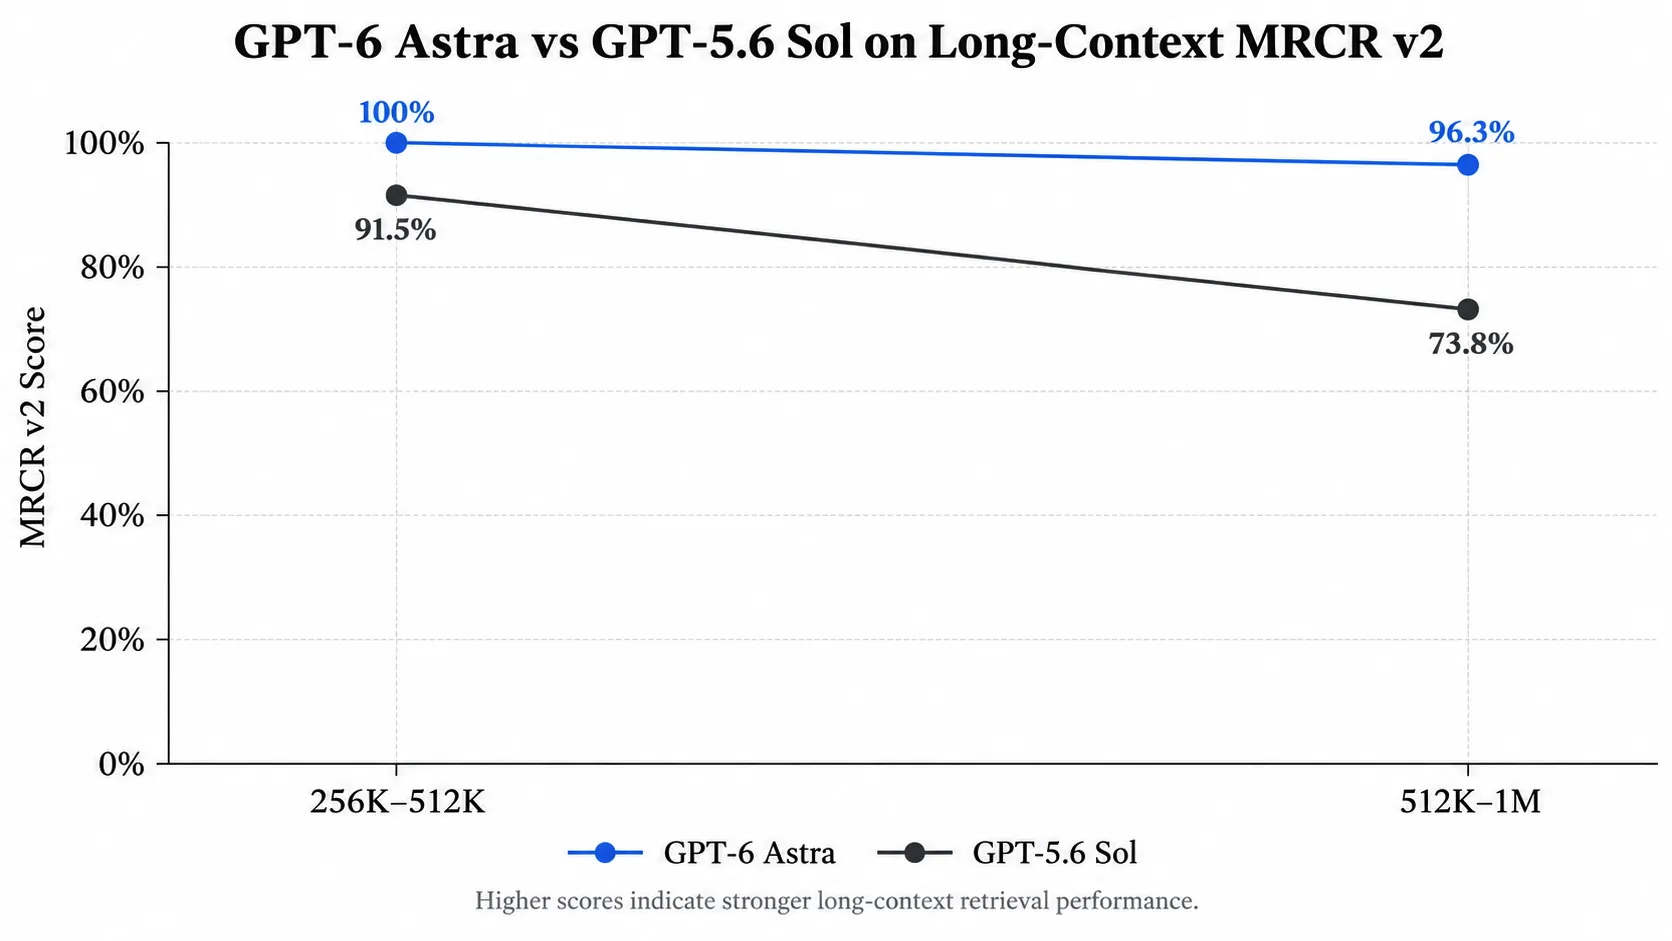
OpenAI’s MRCR v2 results show a larger difference in the longest context range.
| Context range | Astra | Sol |
|---|---|---|
| 256K–512K | 100% | 91.5% |
| 512K–1M | 96.3% | 73.8% |
Both models can accept approximately one million tokens, but Astra was substantially better at retrieving and reasoning across distributed information in the 512K–1M evaluation.
A large context window is not automatically useful. Loading an entire repository without filtering can increase cost, introduce irrelevant information, and push a request into higher pricing tiers.
Astra is most useful when the task genuinely requires relationships across distant files, specifications, documents, logs, and earlier tool results.
Is GPT-6 Astra Better for Coding?
Astra is generally better for difficult agentic coding, architecture diagnosis, and unfamiliar repositories. Sol remains a strong daily coding model and can perform better in specific review or implementation workflows.
Difficult Debugging and Architecture Favor Astra
Our review of developer workflows found recurring cases in which Sol generated plausible local fixes but failed to identify the system-level cause. Astra was more effective when the problem crossed modules, involved unclear runtime behavior, or required inspecting the architecture before editing code.
In one workflow examined during our research, Sol could not complete a remote-stash hotkey feature for a game modification, while Astra found a workable implementation path. The case did not provide standardized timing or token data, so it cannot prove a universal advantage. It does illustrate the type of blocked, unfamiliar problem that justifies escalating to Astra.
Another comparable debugging case produced a smaller Astra change: approximately 120 added and 200 removed lines, compared with 400 added and 100 removed lines for Sol. Diff size is not a quality score, but a smaller change can reduce review risk when both approaches achieve the same result.
Sol Can Remain Better for Code Review
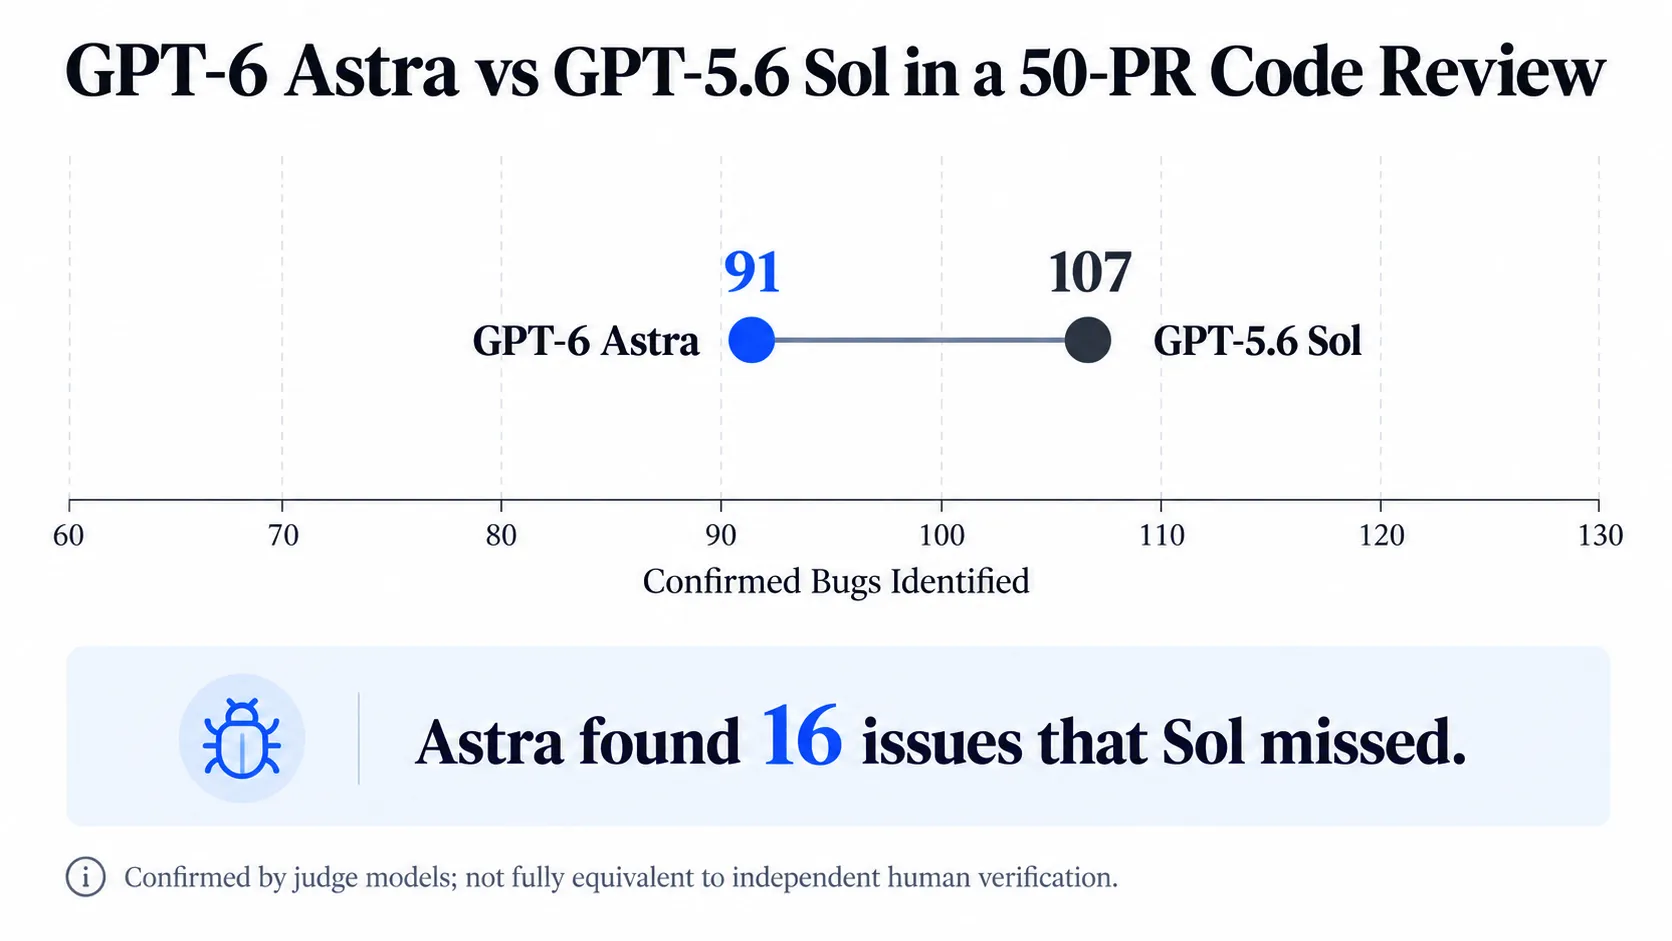
A third-party research project reviewed in our analysis evaluated 50 real pull requests across repositories including Cal.com, Sentry, Discourse, Keycloak, and Grafana using GPT-5.6 Sol.
Sol identified 107 confirmed bugs, while Astra identified 91. Astra found 16 issues that Sol missed and produced higher precision with lower latency in that setup.
The findings were evaluated using judge models rather than complete independent human verification, so the totals should not be treated as a definitive coding LLM leaderboard.
The practical lesson is that stronger overall reasoning does not guarantee broader bug coverage. Sol can remain valuable as an independent verification model, particularly when exhaustive edge-case review matters.
Large Repositories Favor Role Separation
One large-repository audit reviewed during our research used six Astra Ultra runs of roughly 20 minutes each, followed by one Max implementation run and three parallel Ultra red-team reviews.
Over approximately 3.5 hours, the reported weekly allowance moved from 39% to 26%. The workflow created substantial analysis depth but was too expensive to use as a default development pattern.
A more efficient structure is to use Astra for repository mapping, root-cause diagnosis, and planning; a lower-cost model for implementation; and Sol for final verification.
Use Astra for decisions that shape the repository, not necessarily for every file modification.
GPT-6 Astra vs GPT-5.6 API Pricing
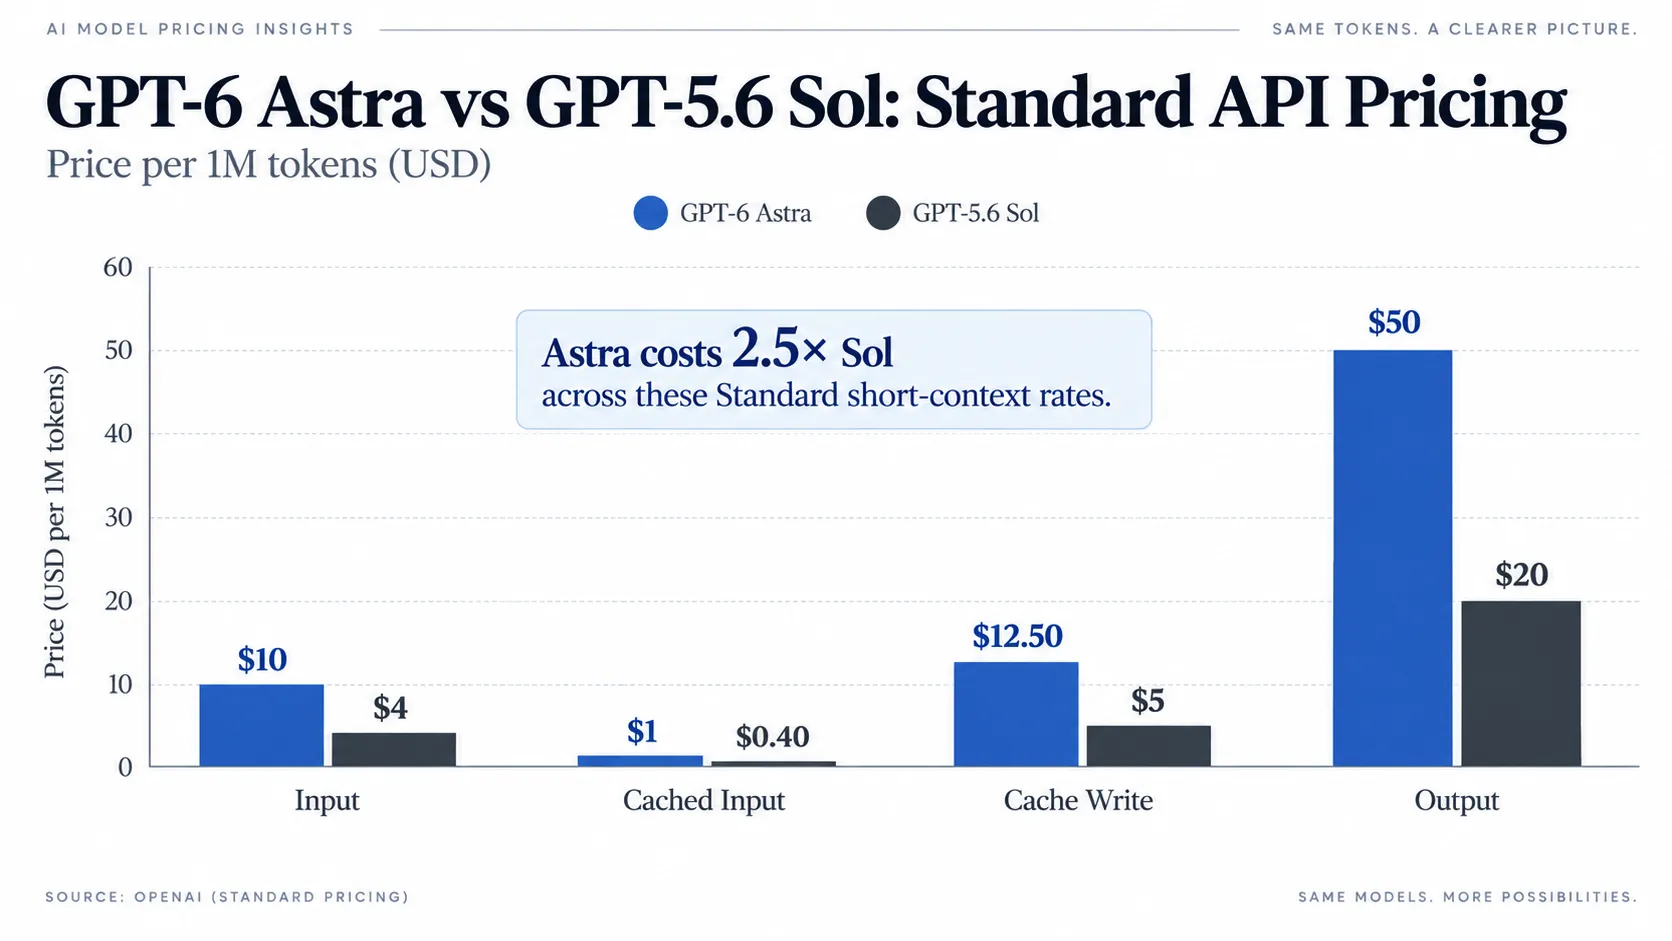
At OpenAI’s current Standard rates, Astra costs 2.5× more than Sol.
| Token type | Astra | Sol |
|---|---|---|
| Input | $10/M | $4/M |
| Cached input | $1/M | $0.40/M |
| Cache write | $12.50/M | $5/M |
| Output | $50/M | $20/M |
Sol’s current promotional pricing is listed as available at least through November 21, 2026, so the comparison should be checked again after that date.
The Same Token Workload Costs 2.5× More
For a request using 100K uncached input tokens and 10K output tokens, Astra costs:
- $1.00 for input
- $0.50 for output
- $1.50 in total
The same workload costs:
- $0.40 for Sol input
- $0.20 for Sol output
- $0.60 in total
This is a calculated estimate based on published Standard token rates, not an official fixed price per request.
If both models consume the same tokens and produce the same accepted result, Sol is clearly more economical. Astra only closes the gap when it uses fewer effective tokens, avoids retries, completes more tasks, or reduces human correction.
The detailed GPT-6 API pricing analysis covers processing modes and cost formulas, while the 272K pricing analysis explains how long-context pricing can increase the cost of an entire request.
Cost per Completed Task Matters More
In the Artificial Analysis index version reviewed on September 15, 2026, Astra Max cost $7.09 per coding-agent task, approximately 15% more than Sol Max, while scoring seven points higher. Astra used roughly one-third as many tokens per task in that evaluation.
Its broader Intelligence Index produced a different result. Astra Max cost $3.26 per task, compared with approximately $1.99 for Sol Max. Astra scored 53 versus 47 but remained more expensive.
These are evaluation-specific results, not universal API costs. They show that model economics change with the workload, reasoning level, agent harness, tool use, and required output.
Cost per successful task equals total model and tool cost divided by accepted results.
Real Workflows Can Reverse the Price Comparison
Our review of a published 11-day usage log covering approximately 6,500 Codex requests and 670 million tokens found that Astra averaged a 61.2K-token prompt, 417 output tokens, and approximately $0.167–$0.174 per request. Sol averaged a 137.8K-token prompt, 831 output tokens, and approximately $0.155 per request.
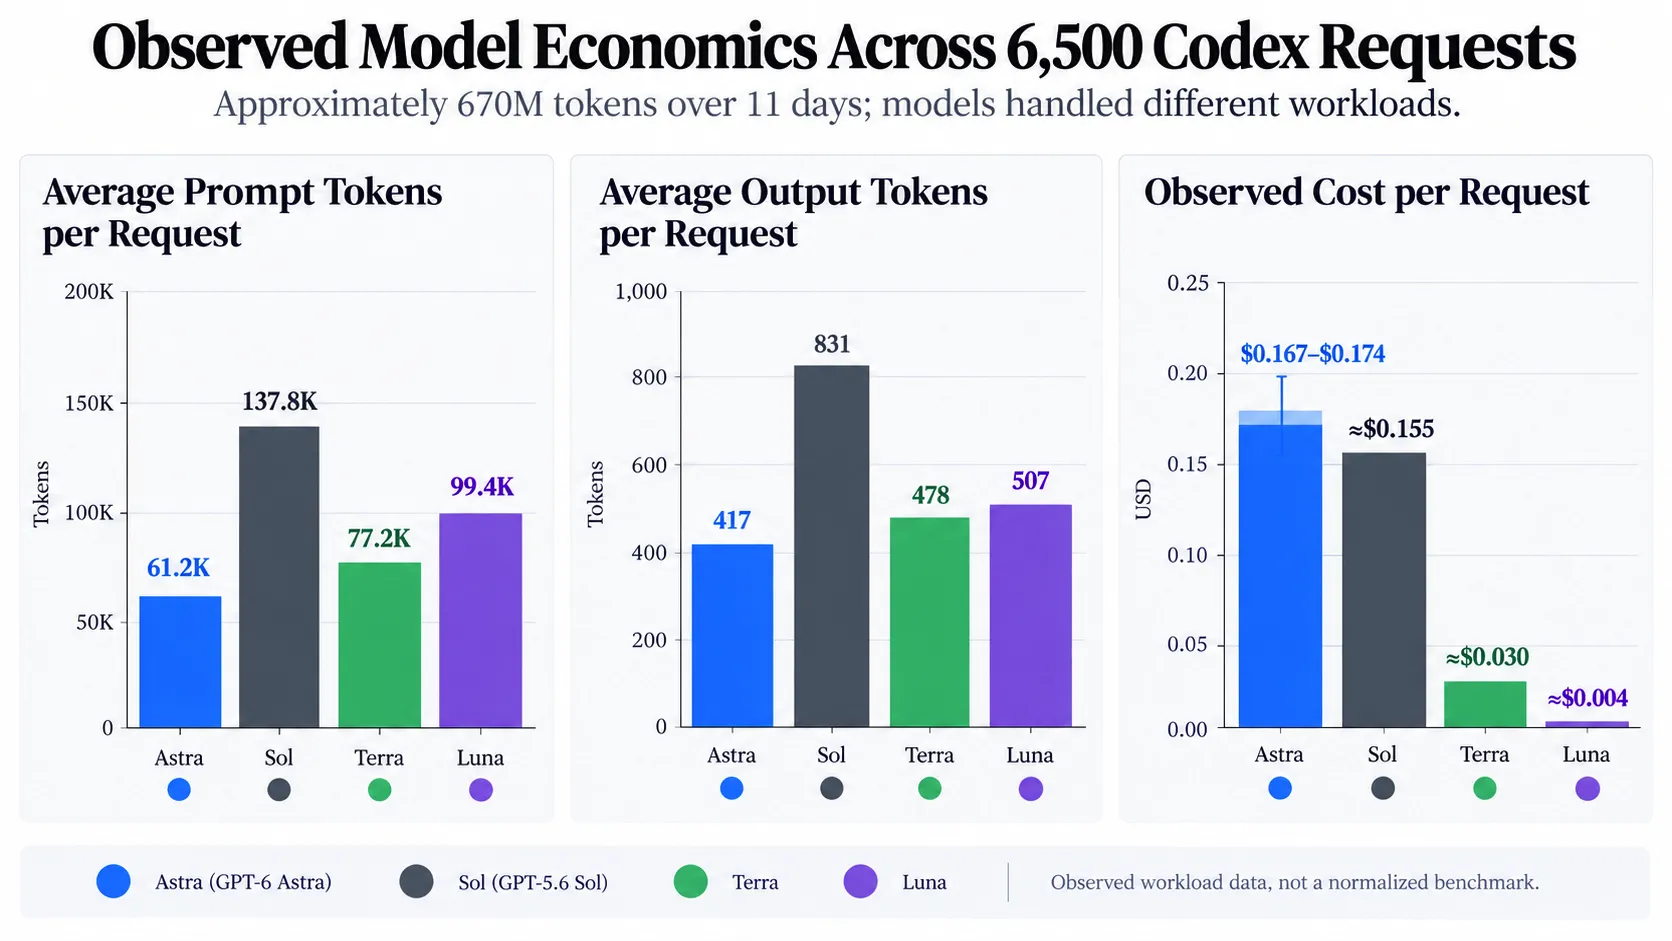
The models handled different tasks, so the log is not a normalized benchmark. It still shows how lower token consumption can narrow Astra’s per-request premium.
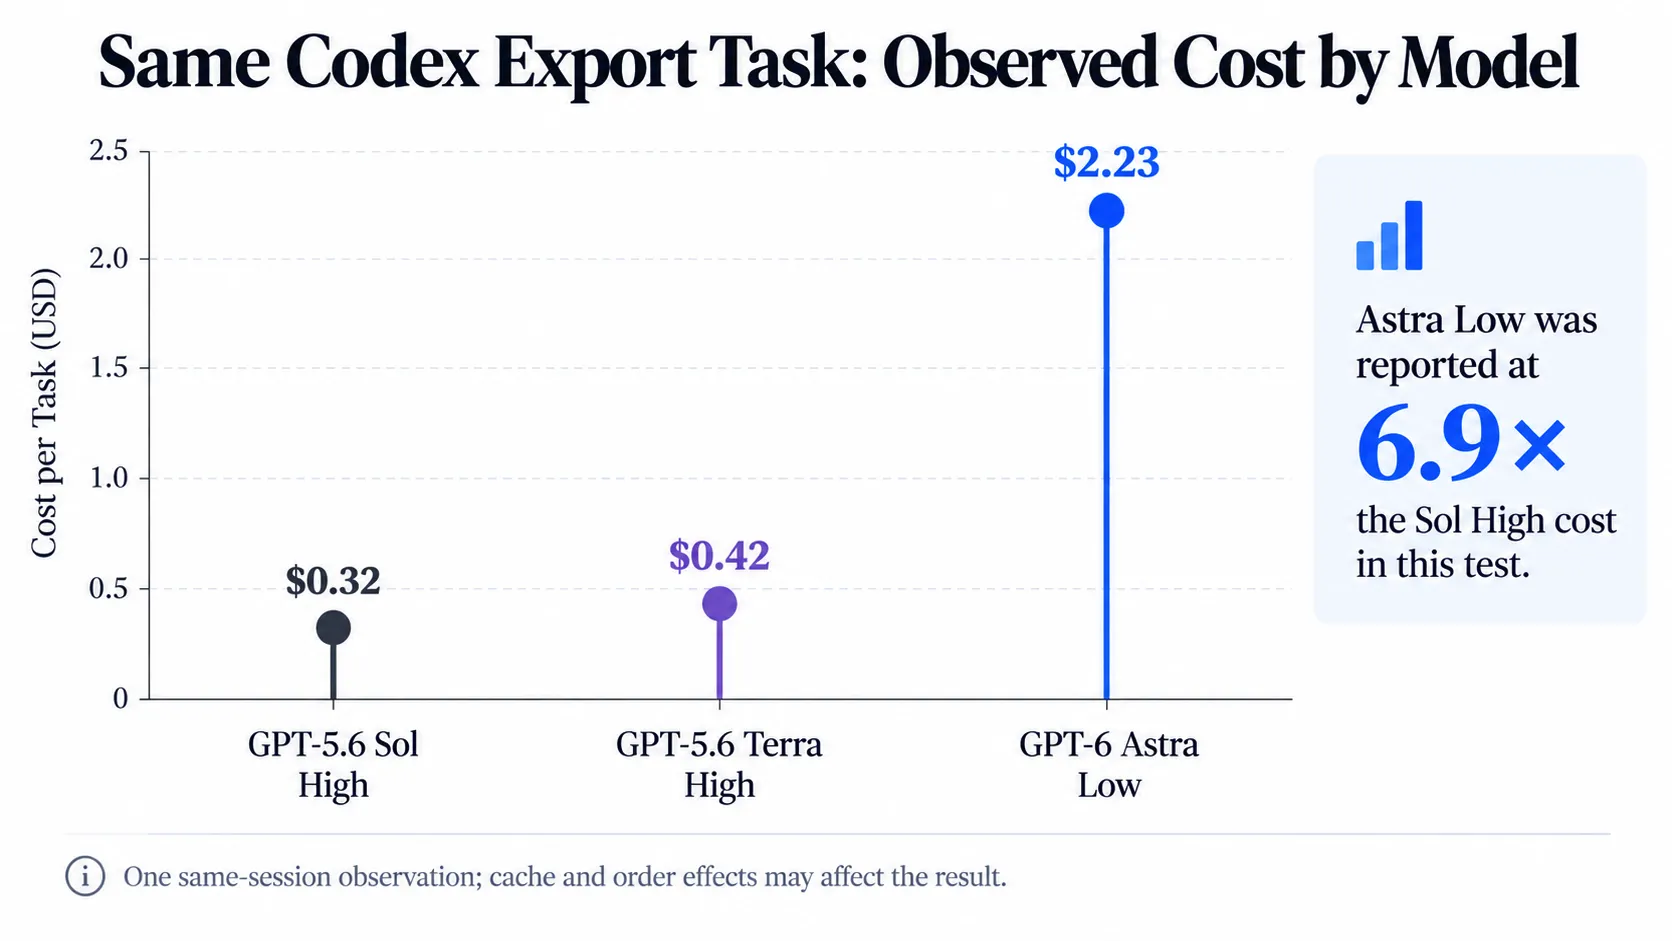
The opposite occurred in a simple conversation-export workflow. Astra Low cost $2.23, Sol High cost $0.32, and Terra High cost $0.42. Astra was approximately 6.9× the Sol cost for a task that did not require frontier-level reasoning.
This is where Astra becomes wasteful: high capability applied to low-complexity work. Teams running large workloads can also reduce spend through AI API cost optimization.
On LinkModel, GPT-6 Astra is priced at $7.50/M input and $37.50/M output for short-context usage, equivalent to 75% of OpenAI’s corresponding Standard token rates.
Why Does GPT-6 Astra Consume Quota So Quickly?
API token charges and ChatGPT or Codex subscription allowances are different systems. A percentage of a weekly allowance cannot be reliably converted into an API invoice.
Reasoning Effort Can Expand the Workflow
Astra supports low, medium, high, xhigh, and max reasoning. Higher settings can increase exploration, verification, tool calls, output tokens, and elapsed time.
In one long coding workflow reviewed during our research, approximately 15 minutes of Astra Medium consumed a five-hour allowance, followed by another 30 minutes that exhausted the reported weekly allowance. Two resets were used without completing the task.
Another single-page workflow using Astra High reportedly consumed an entire five-hour window. These are individual workflow observations rather than official quota rules, but they demonstrate why high reasoning should not become the automatic default.
Higher Reasoning Is Not Automatically Better
Our review found that Astra Low or Medium often provided the best balance for debugging and orchestration. High or max was more appropriate when a task required repeated verification, unfamiliar architecture, or expensive failure recovery.
In one orchestration comparison, Astra Low completed the workflow approximately 41% faster than Sol High. However, Astra still missed a timeout-liveness bug that Sol detected.
Faster completion and stronger overall reasoning did not eliminate the value of a second-model review. Reasoning effort should be increased after a validation failure—not simply because a higher setting is available.
The Best GPT-6 and GPT-5.6 Model Routing Strategy
The most cost-effective strategy is not selecting one permanent winner. It is assigning models to different roles and escalating only when necessary.
Use Sol as the Daily Driver
Sol is the better starting point for:
- Routine coding
- Clear feature implementation
- Documentation and writing
- Predictable analysis
- High-volume API workloads
- Independent code review
- Tasks that already pass validation consistently
Sol’s lower token price gives it a clear advantage when it can complete the request without repeated failures.
Use Astra as the Escalation Model
Astra is the stronger starting point for:
- Unknown root causes
- Repository-wide reasoning
- Database migrations
- Complex computer use
- Multi-tool workflows
- Cross-document analysis
- Tasks that repeatedly fail with Sol
- High-value work requiring less human correction
A practical routing policy is to start with the lowest-cost model likely to succeed, validate the result, and escalate to Astra when the output fails a test or crosses a predefined risk threshold.
Model Routing Can Reduce Usage
One workflow in our research used Astra for difficult reasoning and Sol helpers for routine subtasks. The reported usage rate fell by approximately 50%, extending an estimated one-to-two-day working window to roughly three or four days.
Parallelism alone was less effective. Another workflow ran five worktrees using Sol for difficult tasks, Terra for medium tasks, and Luna for simple tasks. It consumed approximately 50% of a five-hour allowance, yet none of the five tasks finished—a useful reminder when deciding how to choose an LLM for different workload tiers.
More active agents did not create more completed work. The correct optimization target is validated task completion—not token throughput, agent count, or visible activity.
Developers can access GPT-6 Astra through LinkModel alongside GPT-5.6 and other supported models through one OpenAI-compatible API and unified billing, reducing the integration work required to change models.
Who Should Choose Astra or Sol?
Choose GPT-6 Astra If You Need
Choose Astra when your work depends on difficult root-cause analysis, autonomous execution, database migration, repository-wide reasoning, long-context retrieval, or repeated tool use.
It is particularly valuable when failed runs create expensive engineering time, delayed releases, broken workflows, or repeated human correction.
Choose GPT-5.6 Sol If You Need
Choose Sol when you need a reliable daily coding model, predictable professional writing, clear feature implementation, lower token prices, or sustained high-volume usage.
Sol is also useful as an independent reviewer after Astra completes a difficult task because its different behavior may reveal edge cases that Astra overlooked.
Use Both for Production Workloads
Teams should evaluate both models on the same representative task set and measure:
- Successful completion rate
- Input, cached, and output tokens
- Tool actions
- Retry count
- Elapsed time
- Human correction time
- Cost per accepted result
Astra should become the default only for workload categories where these measurements show a material improvement.
FAQ
Is Astra Much Better Than Sol?
Astra is substantially better on some agentic, migration, computer-use, and long-context tasks, but only slightly better on several conventional coding evaluations. It should not automatically replace Sol for every request.
Is Astra Worth 2.5× More?
Astra is worth the higher token price when it measurably reduces retries, failed runs, completion time, or human correction. If Sol already completes the workload reliably, Sol is usually more economical.
Should I Use Astra Low or Sol High?
Start with Sol High for clear implementation and Astra Low for difficult diagnosis or tool-heavy workflows. Test both on the same tasks because reasoning levels are not directly comparable across models.
Why Does Astra Burn Quota So Fast?
Long context, higher reasoning effort, repeated tool calls, parallel agents, and extended workflows can all increase subscription usage. ChatGPT or Codex quota consumption should not be converted directly into API dollars.
Which Model Is Best for Daily Coding?
Sol is the better daily default for most developers. Astra is better used as an escalation model for architecture, difficult debugging, large repositories, migrations, and tasks Sol cannot complete reliably.
Conclusion
GPT-6 Astra is the stronger model for difficult end-to-end work, but GPT-5.6 Sol remains the more efficient default for routine coding and professional tasks. Astra’s largest gains appear in terminal use, automation, migrations, computer use, and demanding long-context workflows—not every coding task. The best production strategy is to measure cost per successful task, begin with the lowest-cost model likely to succeed, validate the result, and escalate to Astra when failure becomes more expensive than additional intelligence. LinkModel supports this approach with GPT-6 Astra at 75% of OpenAI’s corresponding API token rates, GPT-5.6 access, one OpenAI-compatible API, one API key, and unified billing.