For standard, real-time Claude Haiku 5.5 API access, LinkModel lists rates 15% below Anthropic's published Standard token prices: USD 0.085 per million input tokens and USD 0.425 per million output tokens for requests in the up-to-100K pricing tier. Anthropic's corresponding rates are USD 0.10 and USD 0.50. For eligible asynchronous work, Anthropic Batch is cheaper at USD 0.05 and USD 0.25 per million tokens, but it is not a direct replacement for interactive API calls.
The cheapest token rate is not necessarily the cheapest completed task. Longer prompts, cache writes, gateway fees, retries, and failed requests can change your total bill. Compare providers using actual context length and billing conditions, not just headline prices. See the Claude Haiku 5.5 pricing guide and prompt caching guide for additional cost considerations.
LinkModel is worth evaluating when you need real-time Claude Haiku 5.5 access at a lower listed token price. Its Claude Haiku 5.5 model page publishes the discount. Before moving production traffic, confirm current pricing, required API features, data-handling terms, and performance for your workload.
Updated October 12, 2026. This article compares published prices and externally reported examples. It does not claim independent latency, uptime, security, or invoice testing.
Cheapest Claude Haiku 5.5 API Providers: Quick Comparison
For synchronous requests in the up-to-100K tier, LinkModel's listed rates are 15% below Anthropic Standard. Anthropic Batch offers lower published token rates for eligible asynchronous processing. However, no provider is proven cheapest for every workload after fees, features, and task outcomes.
| Access route | Input / 1M tokens | Output / 1M tokens | Best use case |
|---|---|---|---|
| LinkModel Standard | USD 0.085 | USD 0.425 | Lower-priced real-time API access |
| Anthropic Standard | USD 0.10 | USD 0.50 | Direct developer access |
| Anthropic Batch | USD 0.05 | USD 0.25 | Eligible asynchronous workloads |
| OpenRouter-listed endpoints | USD 0.10 | USD 0.50 | Multiple routing options |
| Direct cloud platforms | Account-specific | Account-specific | Existing cloud integrations |
Prices are in USD per million tokens for the short-context tier. Figures exclude taxes, cache writes, and additional charges. OpenRouter prices reflect reviewed endpoint listings, not independently verified direct-cloud account quotes.
Which Route Should You Choose?
For interactive applications, compare LinkModel's published discount with Anthropic direct access and your current gateway. For offline extraction, classification, or queued summarization, Anthropic Batch may offer lower token costs.
If your application already runs on a cloud platform, compare account-specific regional pricing and integration costs. For multi-model applications, gateway convenience and fees also matter. The LinkModel vs OpenRouter comparison explores those broader differences.
Why OpenRouter's Endpoint Prices Are Not Direct-Cloud Quotes
The reviewed OpenRouter listings showed Anthropic, Google Vertex, Amazon Bedrock, Azure, and Claude Platform on AWS at starting rates of USD 0.10 per million input tokens, USD 0.50 per million output tokens, and USD 0.01 per million cache-read tokens.
These are displayed routing prices. They do not establish that direct purchasing through each cloud platform produces identical invoices.
Is LinkModel Cheaper Than Anthropic for Claude Haiku 5.5?
Yes, on the published Standard token rates compared here. LinkModel lists a 15% discount across both context tiers. This establishes a listed price advantage, not guaranteed lower total operating costs.
| Token category | Anthropic ≤100K | LinkModel ≤100K | Anthropic >100K | LinkModel >100K |
|---|---|---|---|---|
| Input | USD 0.10 | USD 0.085 | USD 0.50 | USD 0.425 |
| Output | USD 0.50 | USD 0.425 | USD 2.50 | USD 2.125 |
| Cache read | USD 0.01 | USD 0.0085 | USD 0.05 | USD 0.0425 |
USD per million tokens. Verify current prices and cache-write conditions on the LinkModel model page.
A lower token rate creates savings when the same workload is billed under equivalent conditions. Unsupported features, additional charges, different cache behavior, or retries can reduce those savings.
What Should You Verify Before Paying LinkModel?
Before purchasing credits or migrating production traffic, verify the model identifier, endpoint, authentication method, SDK compatibility, streaming support, tool-use capabilities, caching behavior, rate limits, and error handling.
Also review privacy and data-retention policies, technical support channels, and refund or credit conditions.
Using the same model name does not automatically guarantee identical API features, latency, or reliability across providers.
Claude Haiku 5.5 API Pricing: Why the 100K Threshold Matters
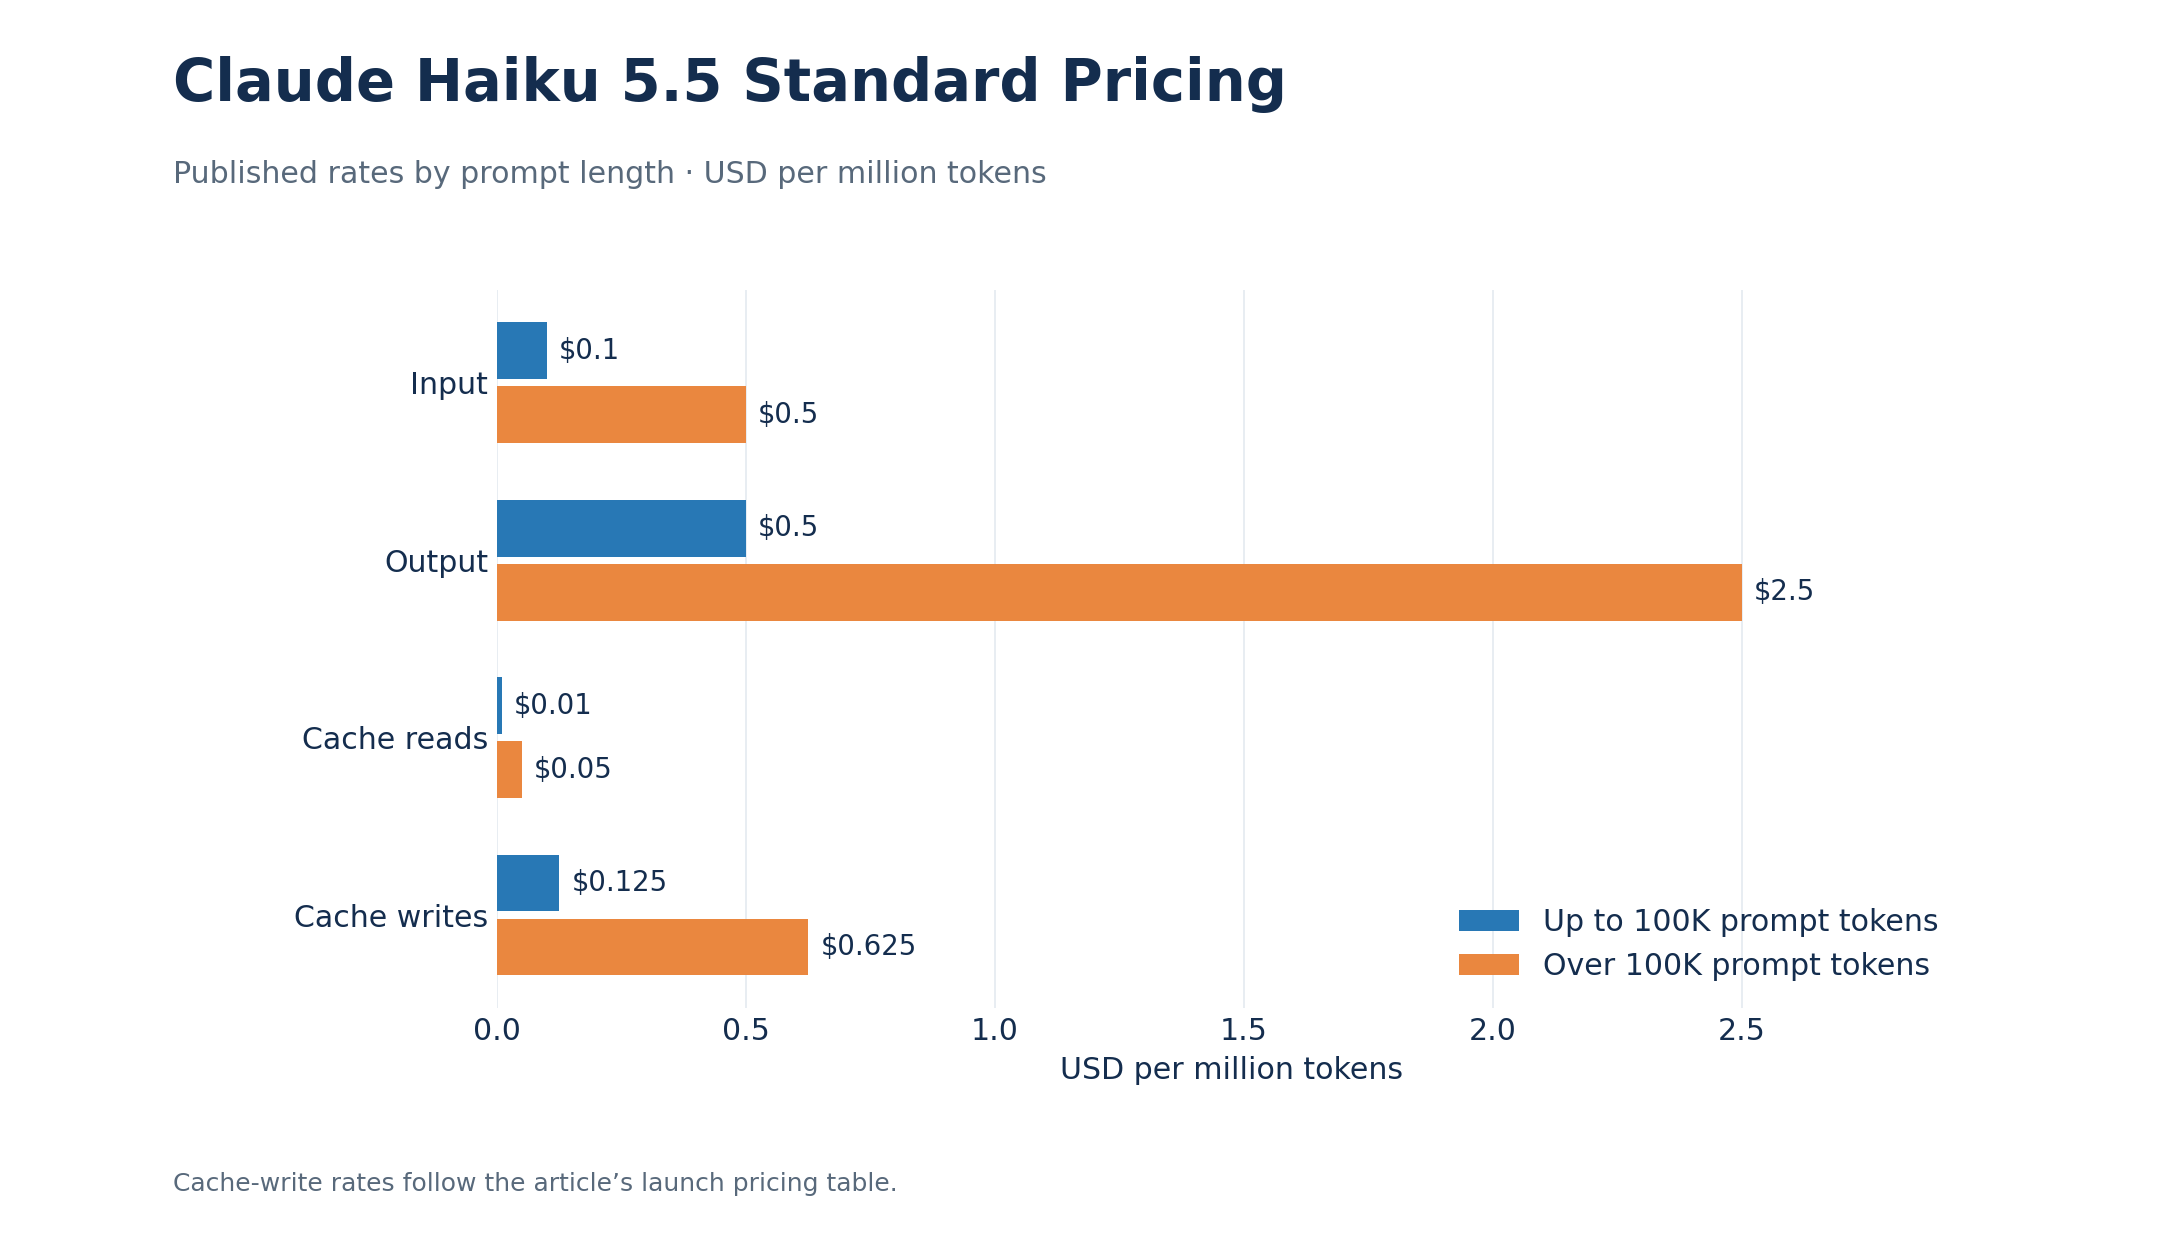
Anthropic's published Haiku 5.5 rates rise fivefold when requests enter the over-100K pricing tier. Estimate costs using the assembled request rather than the latest user message alone.
| Token category | Up to 100K | Over 100K |
|---|---|---|
| Standard input | USD 0.10 | USD 0.50 |
| Standard output | USD 0.50 | USD 2.50 |
| Cache read | USD 0.01 | USD 0.05 |
| Five-minute cache write | USD 0.125 | USD 0.625 |
Anthropic published rates in USD per million tokens. Confirm the selected provider's threshold-counting rules.
Count the Whole Assembled Request
System instructions, conversation history, retrieved documents, tool definitions, and tool responses can substantially increase input-token consumption.
One published agent configuration described approximately 66K startup tokens. Its individually reported components totaled approximately 67,100 tokens:
| Component | Reported tokens |
|---|---|
| System tools | 35,600 |
| MCP tools | 16,600 |
| Skills | 5,900 |
| System prompt | 5,200 |
| MCP instructions | 2,300 |
| Memory files | 1,500 |
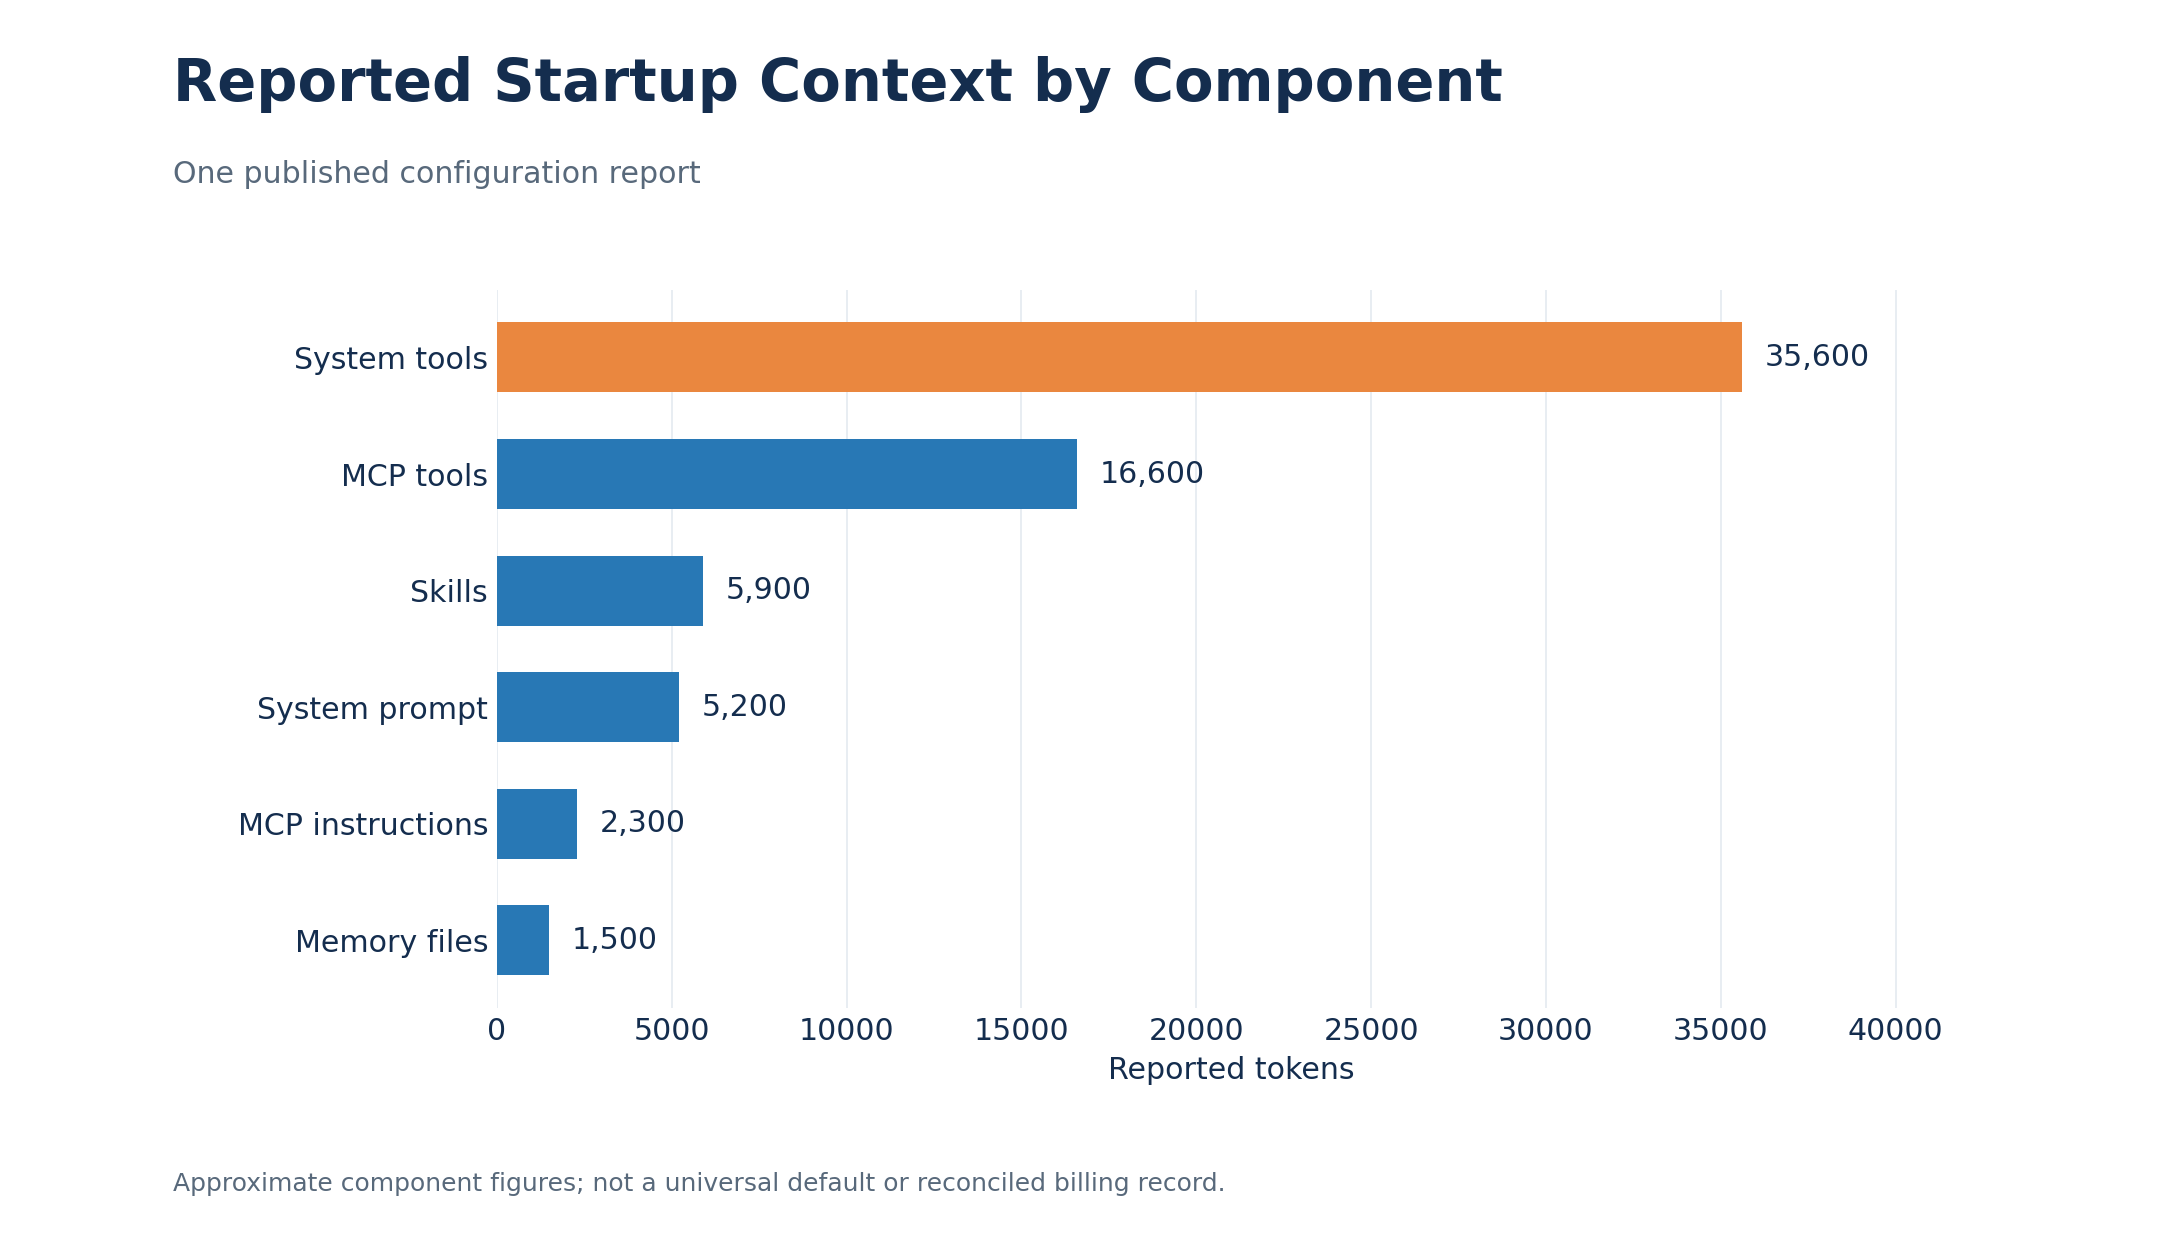
This is one externally reported configuration, not a universal default or verified billing record.
Inspect actual request payloads and usage logs. A model's maximum context window is also different from its pricing threshold, as explained in the context-window comparison.
Region and Deployment Can Change the Quote
The reviewed Anthropic documentation describes a 1.1× multiplier for specified US-only inference arrangements on its first-party API and Claude Platform on AWS, with deployment-specific rules elsewhere.
Regional processing requirements, cloud contracts, and purchasing conditions can outweigh differences in advertised token prices. Confirm the rules applicable to your selected deployment.
Anthropic Batch vs LinkModel: Which Is Actually Cheaper?
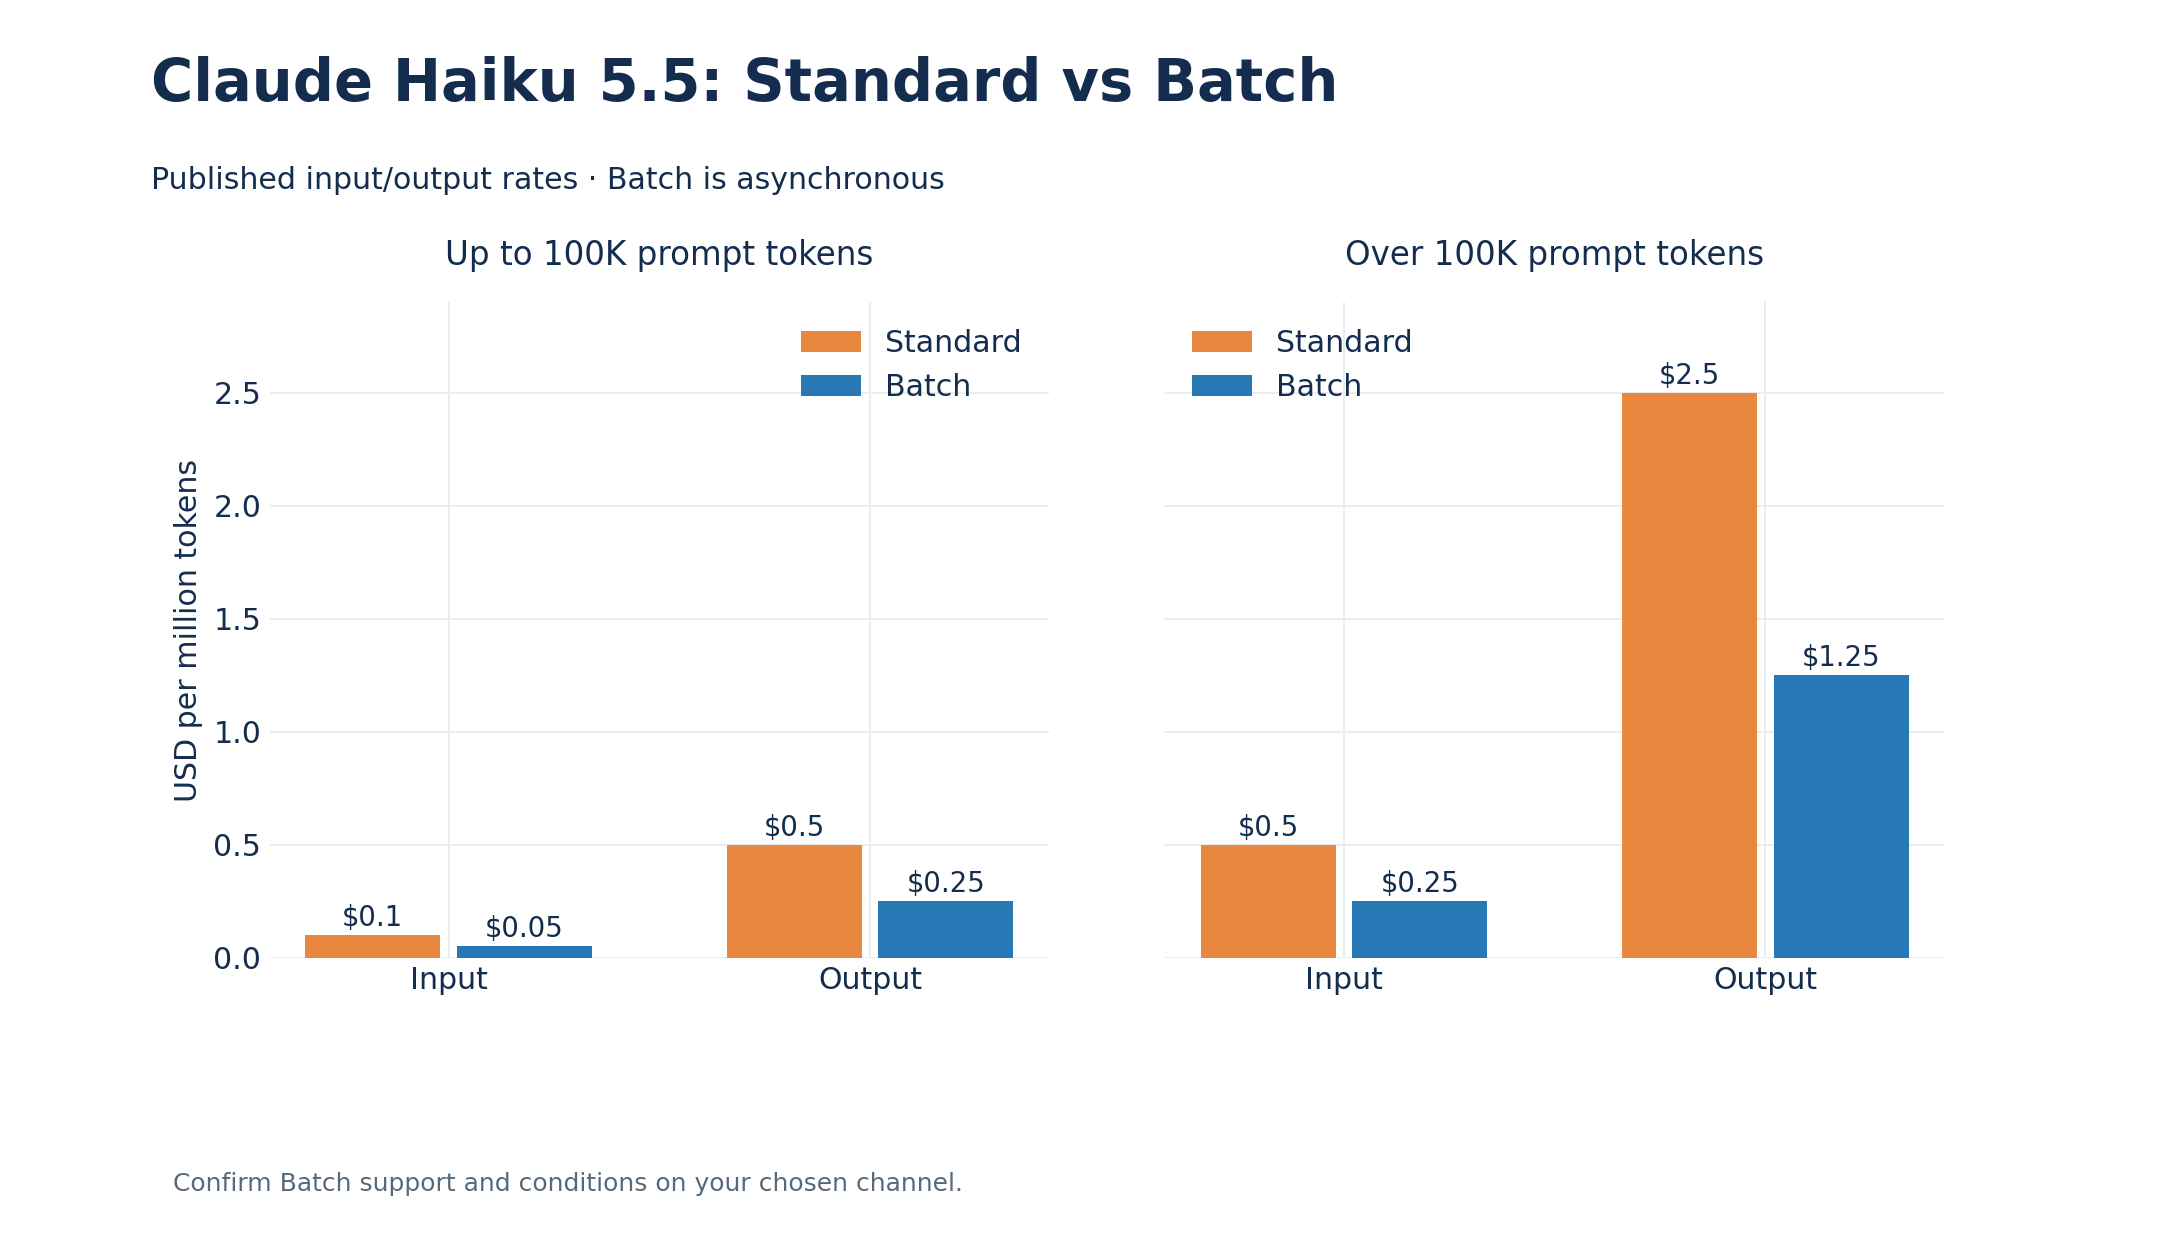
Anthropic Batch has lower published input and output token rates for eligible asynchronous workloads. LinkModel's Standard API is more relevant when an application needs interactive responses.
| Pricing tier | Batch input | Batch output | LinkModel input | LinkModel output |
|---|---|---|---|---|
| Up to 100K | USD 0.05 | USD 0.25 | USD 0.085 | USD 0.425 |
| Over 100K | USD 0.25 | USD 1.25 | USD 0.425 | USD 2.125 |
USD per million tokens. Batch figures reflect published discounted rates; verify eligibility and processing requirements.
Batch can suit scheduled extraction, document classification, and summarization jobs that can wait.
Live chat, interactive tools, and time-sensitive applications require separate latency and feature evaluations.
The cheapest processing mode is not automatically the best option for every application.
How Much Could You Save With LinkModel?
At the published short-context Standard rates, LinkModel reduces model input and output token charges by 15% compared with Anthropic Standard, assuming equivalent billable usage and no additional differences in charges.
Consider an illustrative monthly workload containing 100 million ordinary input tokens and 20 million output tokens, all billed at short-context rates, without caching or additional fees.
| Cost component | Anthropic Standard | LinkModel |
|---|---|---|
| 100M input tokens | USD 10.00 | USD 8.50 |
| 20M output tokens | USD 10.00 | USD 8.50 |
| Total | USD 20.00 | USD 17.00 |
| Savings | — | USD 3.00 (15%) |
This is a mathematical example based on published prices, not an actual customer invoice.
For low-volume applications, the absolute savings may not justify engineering migration costs. For higher-volume workloads, savings scale with equivalent usage.
The AI API cost-reduction guide explores additional optimization approaches.
Include Cache Writes, Reads, and Retries
Anthropic's reviewed short-context pricing lists five-minute cache writes at USD 0.125 per million tokens, one-hour writes at USD 0.20, and cache reads at USD 0.01.
Do not assume that LinkModel offers identical cache-writing durations or discounted write prices without checking its current documentation.
Measure cache hits, cache rewrites, output tokens, retries, and failed requests.
Total task cost matters more than an isolated cache-read price.
Provider Fees: OpenRouter, Direct APIs, and Cloud Accounts
Compare total account charges rather than model-card prices alone.
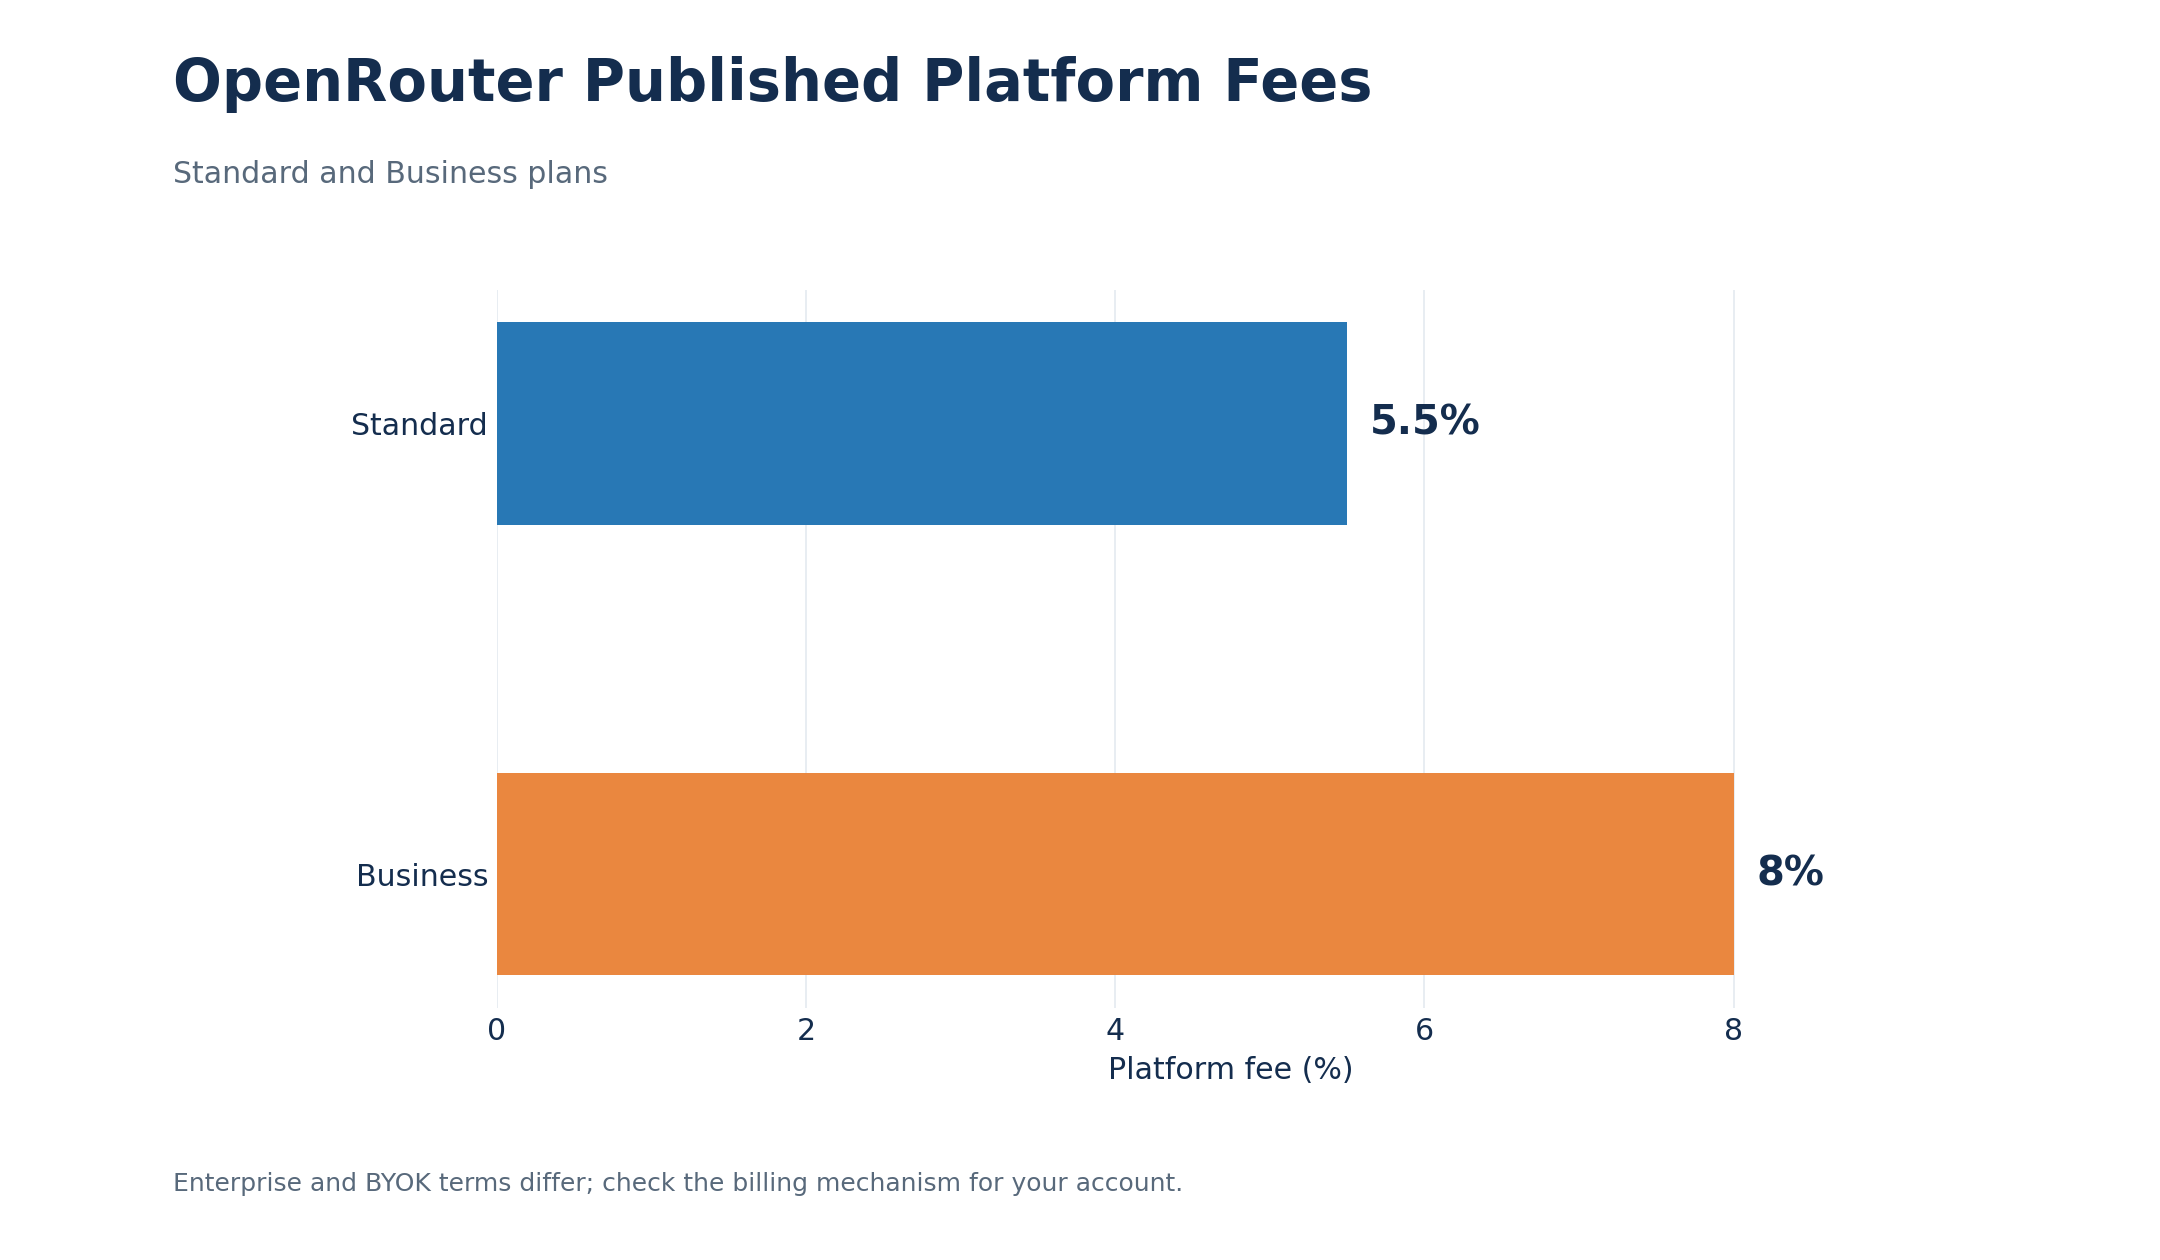
The reviewed OpenRouter pricing materials describe 5.5% Standard and 8% Business platform fees, with separate terms for enterprise and bring-your-own-key arrangements.
Verify how these charges apply, including whether they relate to credit purchases. Do not automatically add the stated percentage as a per-request markup.
Cloud providers may also have regional prices, account commitments, or contract-specific purchasing conditions.
LinkModel advertises pay-as-you-go access and no monthly platform fee. Confirm its current payment, billing, and refund terms before purchasing credits.
A fair comparison should use equivalent request types, regional requirements, cache settings, and billing periods.
What Do Published Tests Tell Us About Real API Cost?
Published model comparisons show why task completion and retries matter, but they do not establish which Haiku 5.5 API provider is fastest or most reliable.
The following examples are third-party workload reports, not independent LinkModel benchmarks.
Voxel Pagoda: Estimated API-Equivalent Spending
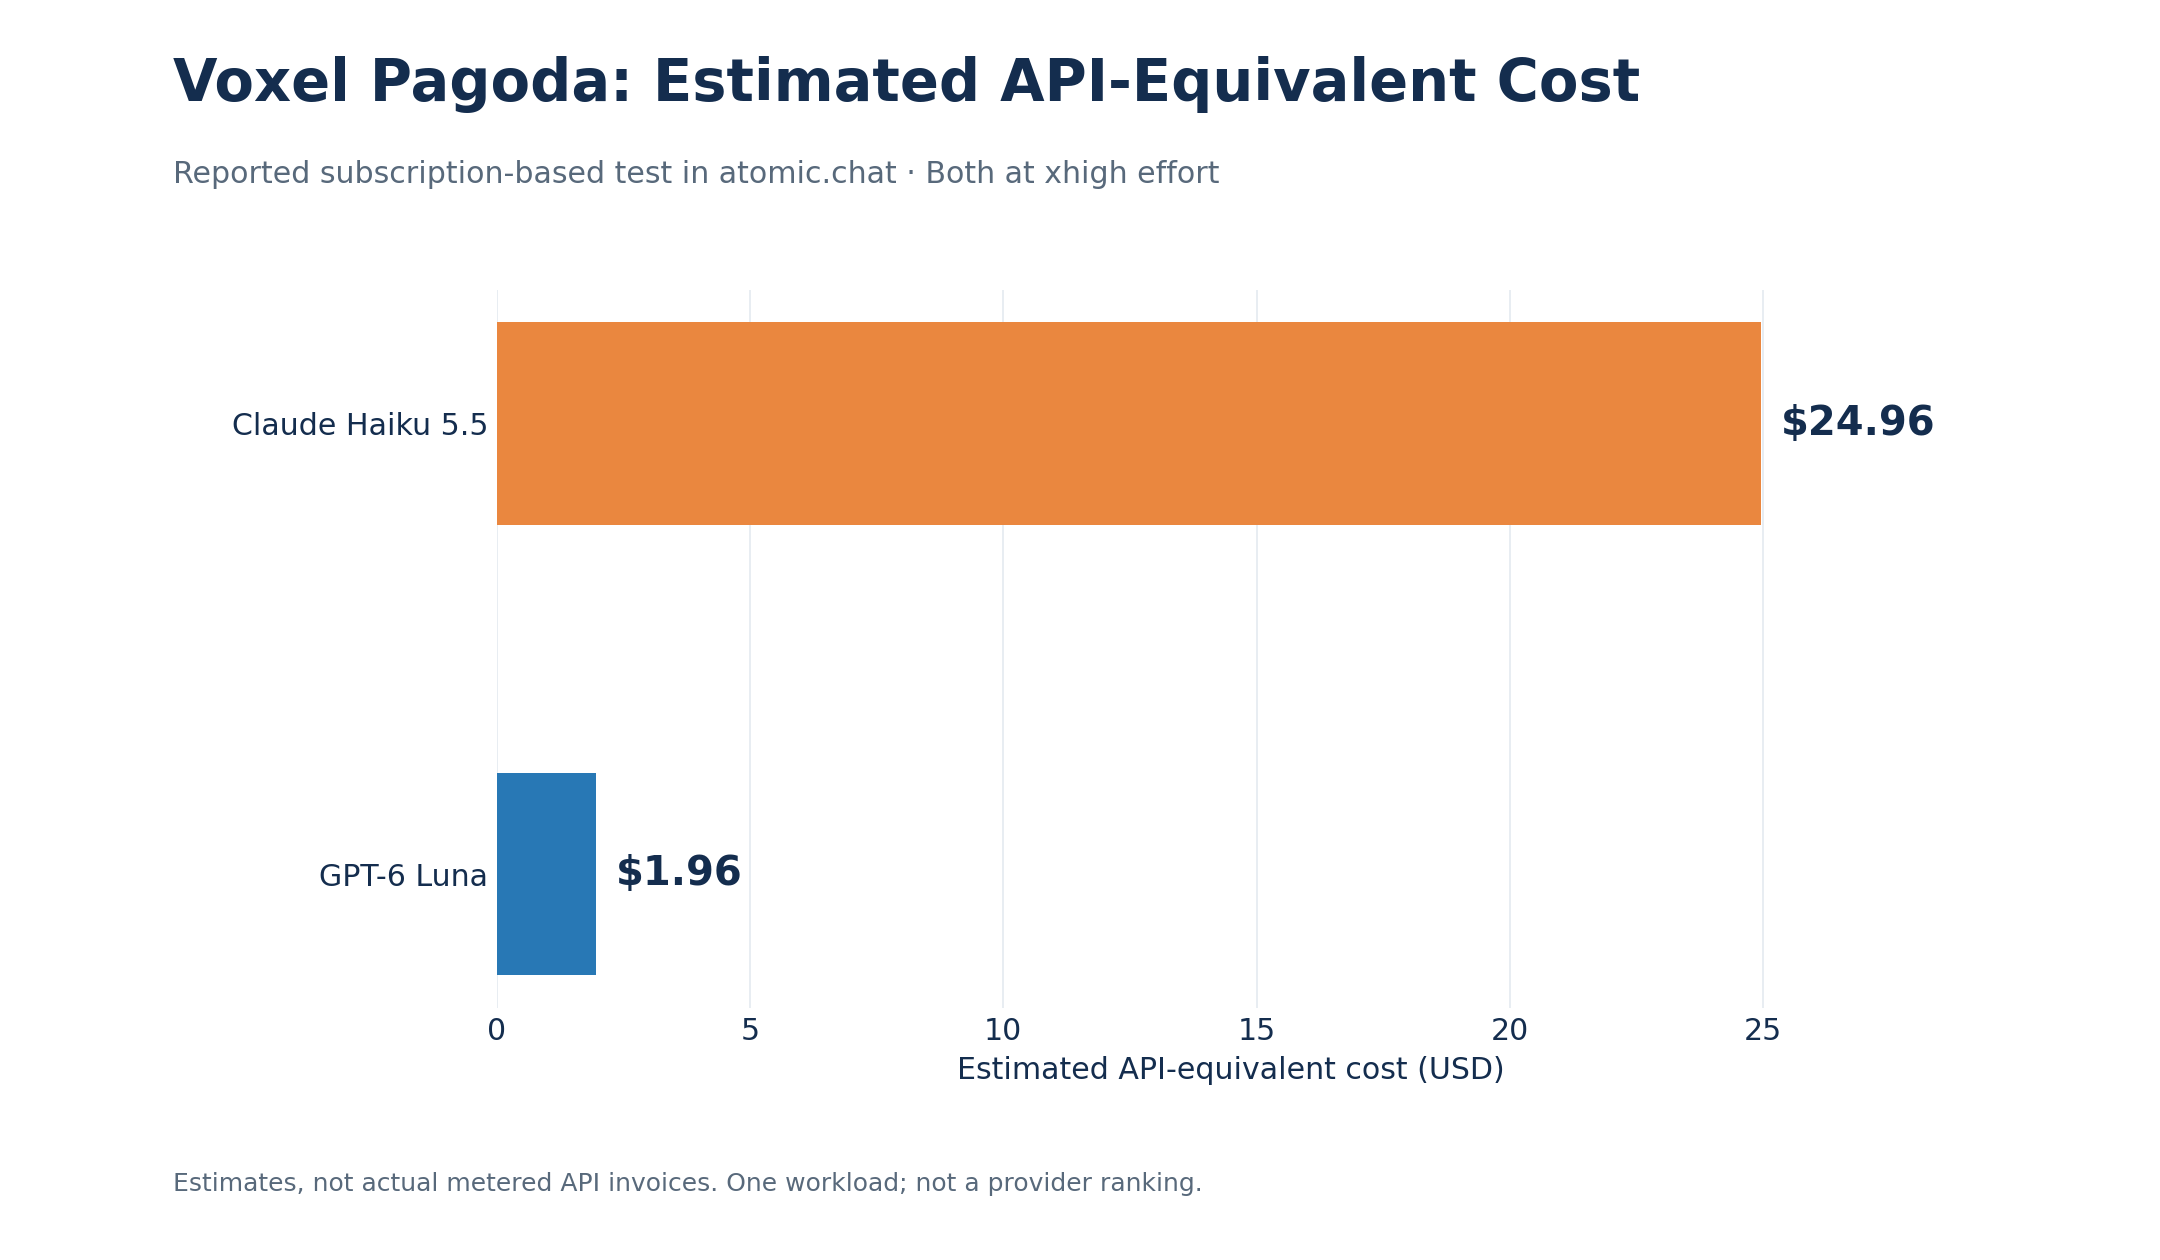
One published voxel-pagoda comparison ran Haiku 5.5 and GPT-6 Luna through subscriptions in atomic.chat, both described as using xhigh effort.
The author reported:
| Metric | Haiku 5.5 | GPT-6 Luna |
|---|---|---|
| Total input | 268.8M | 64.5M |
| Cached input | 262.7M | 61.1M |
| Output | 4.46M | 1.18M |
| Estimated API-equivalent cost | USD 24.96 | USD 1.96 |
The estimated costs differ by approximately 12.7 times.
These figures are not actual metered API invoices, and the experiment was not independently reproduced for this article.
The useful lesson is to measure complete-session token consumption, retries, and successful outcomes rather than focusing on one response.
For model-selection details, see the Haiku 5.5 vs GPT-6 Luna comparison.
Synthetic Scores Are Not Provider Price Tests
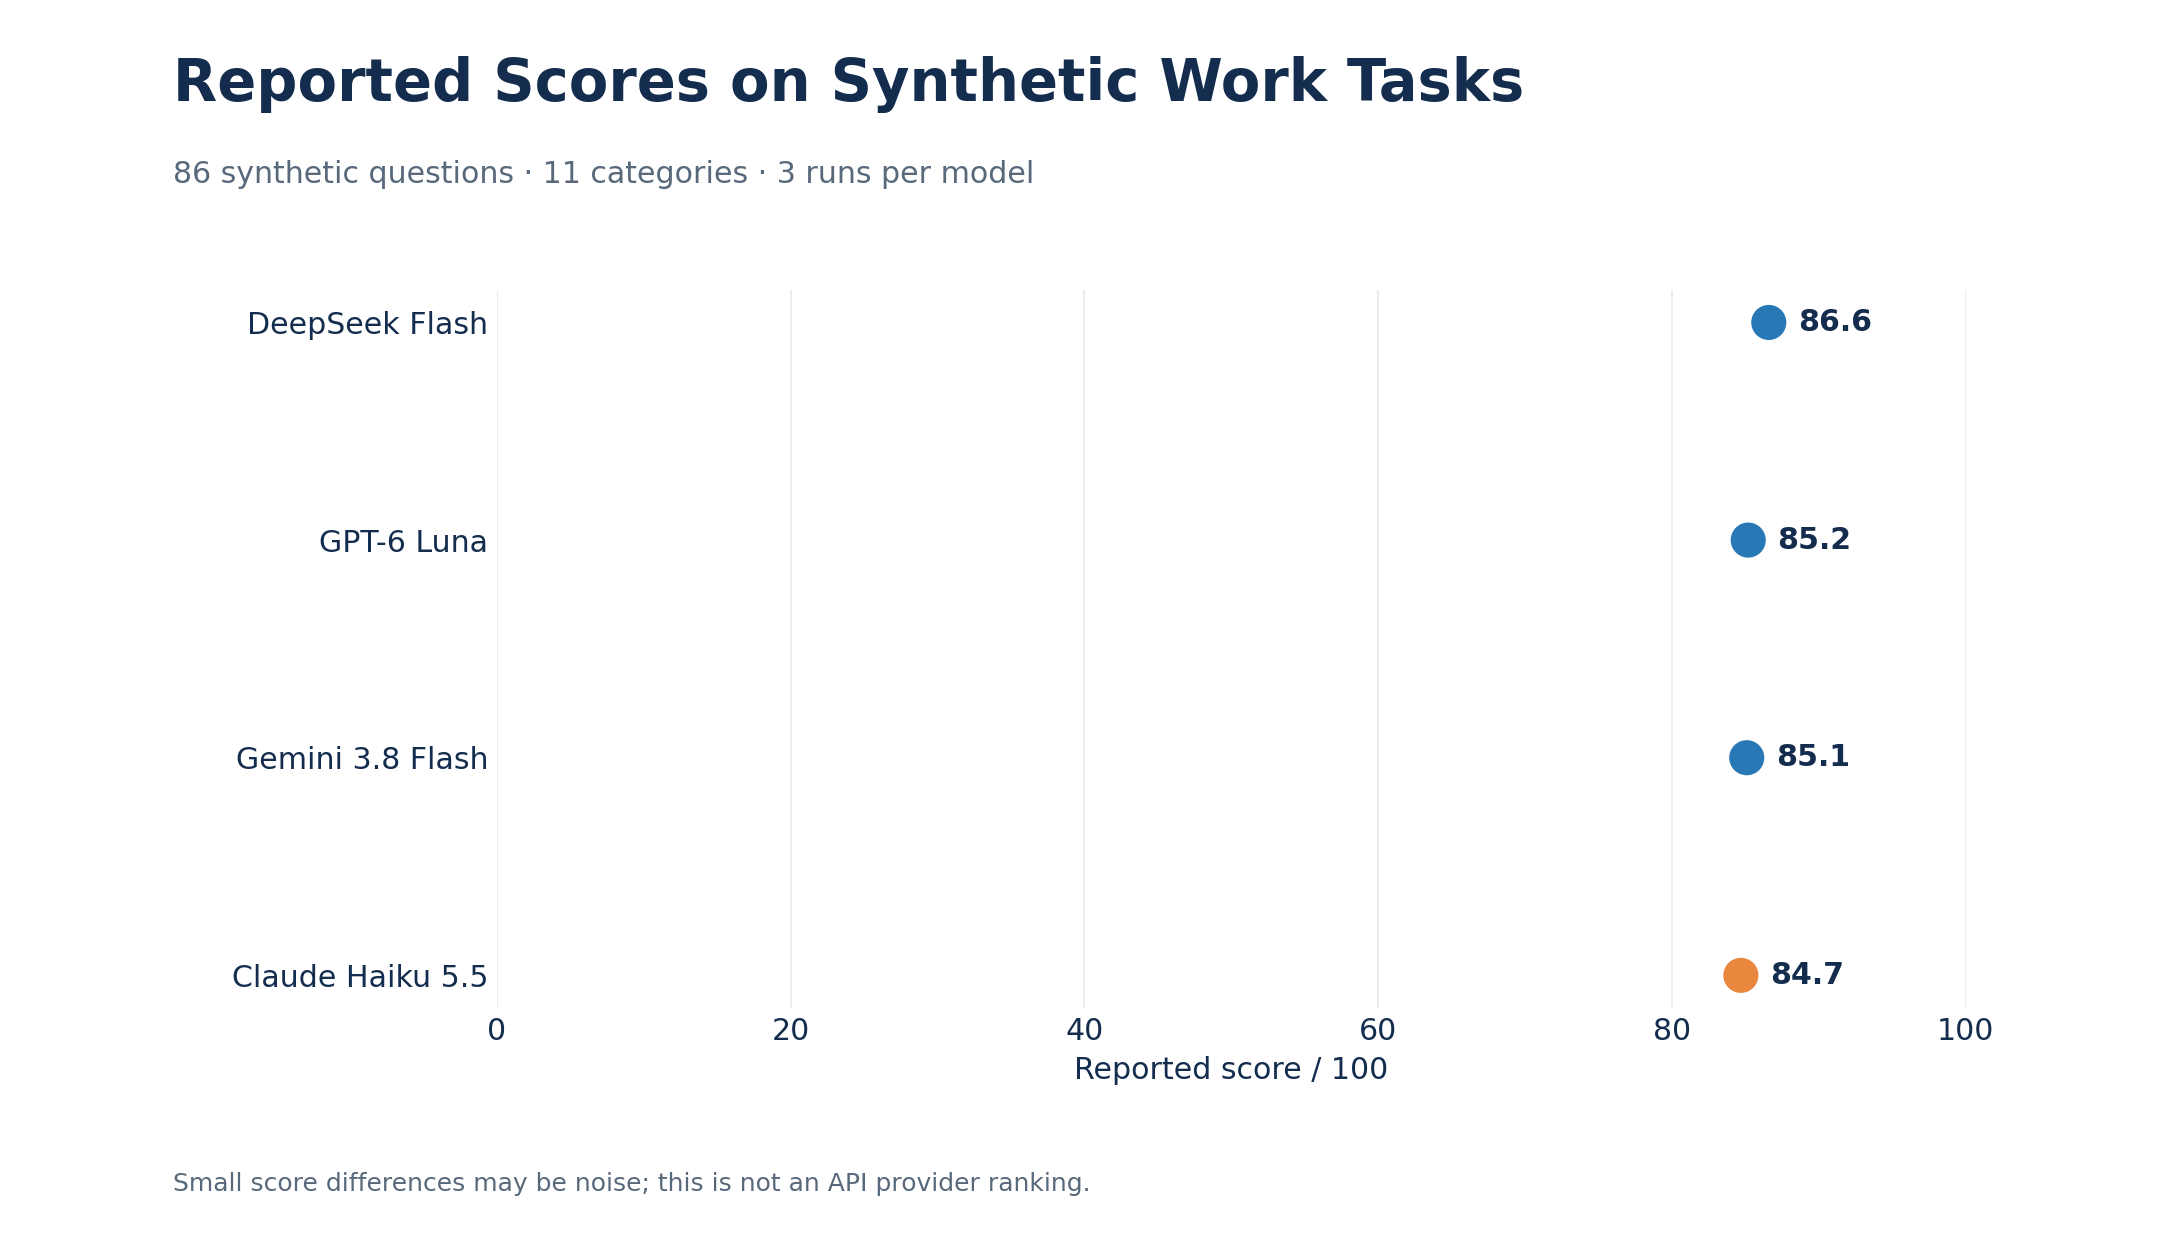
A separate published evaluation covered 86 synthetic questions across 11 categories, with three runs per model.
Reported scores out of 100 were:
| Model | Reported score |
|---|---|
| DeepSeek Flash | 86.6 |
| GPT-6 Luna | 85.2 |
| Gemini 3.8 Flash | 85.1 |
| Claude Haiku 5.5 | 84.7 |
Haiku's reported median completion time was 3.5 seconds. The evaluator cautioned that small score differences could reflect noise.
Haiku was accessed through a subscription, so a zero-dollar harness charge does not establish its API cost.
These results do not demonstrate superior LinkModel speed, quality, or uptime.
How to Evaluate Claude Haiku 5.5 on LinkModel Before Switching
Start with a small representative pilot instead of migrating production traffic solely because of a 15% advertised discount.
The LinkModel Claude Haiku 5.5 page is the starting point for current model pricing and access details.
1. Confirm access and requirements. Verify the model identifier, endpoint, authentication method, account eligibility, supported features, and billing conditions.
2. Select representative requests. Include short prompts, long inputs near the pricing threshold, cached requests if supported, tool calls, and tasks that commonly trigger retries.
3. Keep settings comparable. Use equivalent prompts, response limits, and acceptance criteria where the endpoints permit.
4. Measure actual outcomes. Record latency, successful results, errors, retries, token usage, cache behavior, and charged amounts.
5. Review operational risks. Check privacy policies, data retention, support channels, incident handling, and account conditions before scaling.
Compare Cost per Accepted Result
Cost per accepted result = total billable test spending divided by the number of accepted results.
Define acceptance criteria before testing. Include billed failures and retries, and track human correction time separately.
This provides a more useful purchasing metric than token price alone.
The LLM selection framework offers additional guidance.
| Workload | Evaluate first |
|---|---|
| Real-time chat | LinkModel and Anthropic Standard |
| Offline processing | Anthropic Batch |
| Existing cloud deployment | Current cloud account quote |
| Multi-model applications | Gateway features and fees |
| Long-running agents | Complete-session token usage and retries |
Frequently Asked Questions
Which Claude Haiku 5.5 API Provider Is Cheapest?
The reviewed standard endpoints tie at their starting rates. Anthropic Batch offers lower published input/output rates for eligible asynchronous work. For live requests, compare context tiers, platform charges, and cost per accepted result.
Does the 100K Threshold Apply Only to My Latest Message?
Do not budget from the latest message alone. Instructions, history, tools, and retrieved content can enlarge the assembled request. Verify the endpoint’s exact counting rules and treatment of cached input before relying on a tier estimate.
Does Higher Effort Make Haiku 5.5 Better Value?
Only when improved acceptance justifies additional spending and waiting. Test effort settings separately. Matching effort names across models does not establish equal computational budgets.
Is Haiku 5.5 Faster or Cheaper Than Luna and DeepSeek?
The reviewed cases do not establish a universal winner. They use different tasks, configurations, and billing arrangements. Check the GPT-6 Luna API pricing guide when evaluating that alternative, then compare equivalent workflows. Keep actual API spending separate from subscription usage and API-equivalent estimates.
Why Can a Platform List Haiku 5.5 While My Account Cannot Use It?
A public listing and account access are separate checks. Confirm the exact model, eligible plan, region, permissions, and client support. For LinkModel, obtain model-specific confirmation before treating Haiku 5.5 as an available purchasing option.
Conclusion
The cheapest Claude Haiku 5.5 API option depends on complete workload cost. The reviewed standard endpoints share starting rates, while Anthropic Batch offers lower published rates for eligible asynchronous processing. Compare equivalent deployment conditions, include platform charges, and count all billable attempts required for acceptable results. Explore the LinkModel model catalog to check available options and current prices, then confirm model-specific access and use a representative pilot to choose the lowest-cost route that meets your requirements.